Data sources are the basis for importing data from a source system or a source file into Disclosure Management. To import the desired data into Disclosure Management and use it in reports, the data source must be configured accordingly in the Import Management area.

The following is defined during configuration of the data source in Disclosure Management:

  • Which data from the data source should be taken into account for the import (Parameterization)
  • Which columns contain which data (Mapping)
  • Whether and how certain data should be converted or enriched during the import (Transformation)
  • Whether and how certain data should be summarized during the import (Aggregation)

The configuration of the data source depends on the type of data source (i.e. whether you obtain data from a file, from a Lucanet database or from Lucanet ESG reporting).

The Import Management functional area is only activated for users who have been assigned the Global Administrator role in Disclosure Management role management, as only this user role is authorized to manage imports (ImportData). (For additional information about user roles in Disclosure Management, see Assigning Global Roles for Disclosure Management)

To create a data source in Disclosure Management, you must first define a connection for this data source in the Connections workspace. For additional information, see Defining a Connection to a Data Source. Several data sources can be created with the same connection.

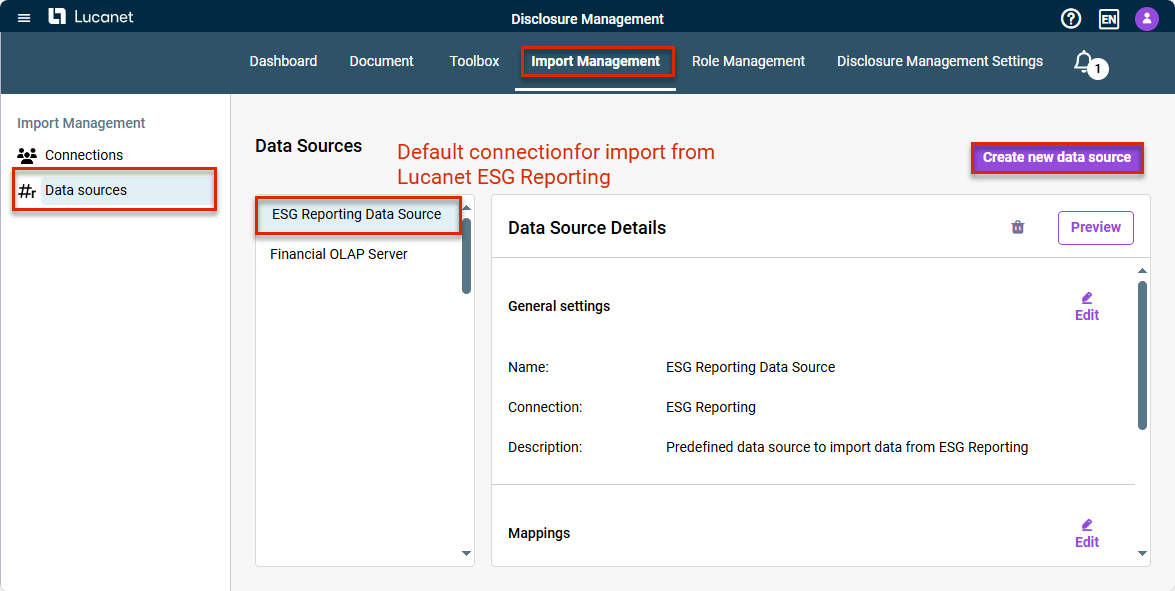
Data sources are created and configured in the Disclosure Management Import Management area:

Shows the 'Data Sources' workspace in the 'Import Management' area of Disclosure Management with the data sources 'ESG Reporting Data Source' and 'Financial OLAP Server' and the 'Data Source Details' with the areas 'General settings' and 'Mappings'. Highlighted in red are 'Import Management', 'Data sources', 'ESG Reporting Data Source' with the annotation 'Default connectionfor import from Lucanet ESG Reporting', and the 'Create new data source' button.
Creating a data source

To create a data source in Disclosure Management:

1

Click in the function bar on Import Management and then in the overview on Data sources to open the workspace.

2

Click Create new data source.

3

Configure the data source as described in the following sections.

4

Save the data source.

An overview of all data sources already created in Disclosure Management is displayed on the left-hand side of the detail view. From here, you can:

  • Create a new data source
  • Select and edit existing data sources

By default, a data source for importing from Lucanet ESG Reporting is already created in the overview, which is preconfigured and can be used by all users who have licensed Lucanet ESG Reporting. For additional information on this data source see section Default Data Source for Importing from Lucanet ESG Reporting.

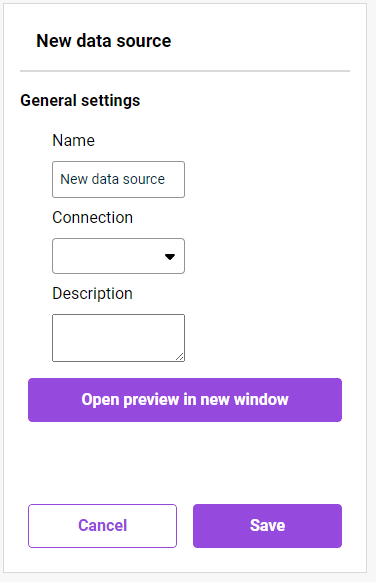
To configure a data source in Disclosure Management, you have to open the edit mode by clicking Edit in the data source's detail view.

Shows the general settings of a new data source in Disclosure Management with the fields 'Name', 'Connection' and 'Description', the 'Open preview in new window' button, and the 'Cancel' and 'Save' buttons.
General settings of a data source

The following table describes the general settings of a data source in Disclosure Management:

OptionDescription
NameName of the data source
ConnectionSelection of the connection to the data source that was previously configured in the Connections workspace.
DescriptionOptional description for the connection
Import parametersArea for defining the import parameters (see section Defining Import Parameters).
CreateCreates the data source or saves the changes made.
  • Several data sources can be created with the same connection.
  • When importing an Excel file, a separate data source must be created for each worksheet.
  • As soon as the connection has been selected, further configuration fields and commands are displayed.
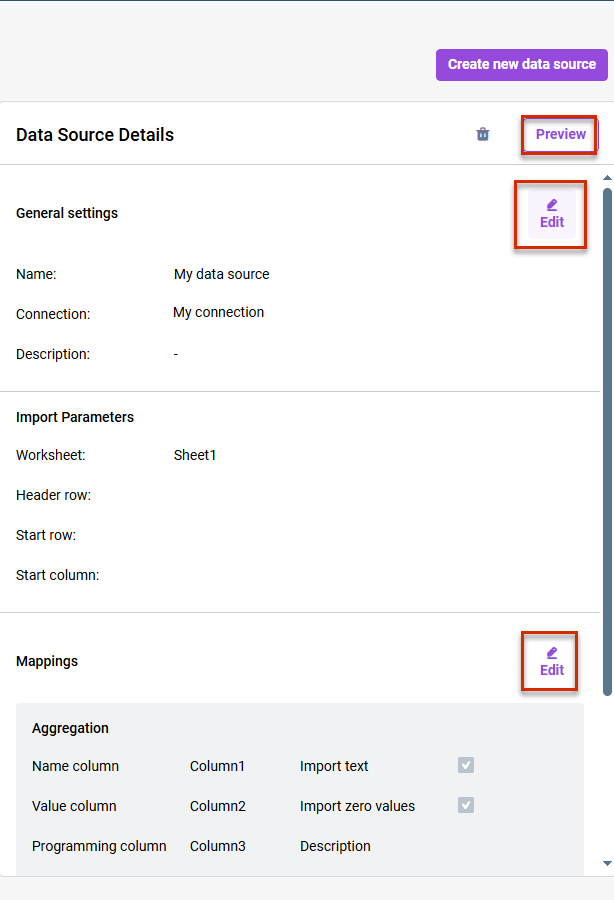
The detail view of a data source in Disclosure Management is displayed as follows, for example:

Shows the 'Data Source Details' of the data source 'My data source' in Disclosure Management with the areas 'General settings', 'Import Parameters' ('Worksheet', 'Header row', 'Start row', 'Start column') and 'Mappings' with the mapping 'Aggregation'. Highlighted in red are the 'Preview' button and the two 'Edit' buttons.
Detail view of a data source

The following functions are available in the detail view of a data source in Disclosure Management:

  • Click Preview to display a preview of the imported data before and after applying the configuration created under Mappings (see section Displaying a Preview of the Imported Data).
  • Click Edit in the General settings area if you want to edit the general properties and/or the Import parameters.
  • Click Edit in the Mappings section if you want to create new mappings or edit or delete existing mappings.

    The area Mappings is used to create one or more mappings for the data source, i.e. Specifications on how the imported data should be assigned within Disclosure Management.

    Transformations and aggregations of the data to be imported can also be configured via the configuration of the mappings (see section Defining Mapping).
  • You can also delete the data source, save it, and cancel editing of the details.

You can use import parameters to specify which data should be imported from a data source into Disclosure Management. The required parameters for this depend on the type of data source (i.e. whether you obtain data from a file, from a Lucanet database or from Lucanet ESG reporting).

In the data source interface, click Import parameters to open the configuration of the import parameters.

An explanation of the parameters that you must or can define for an import is provided on the user interface.

When importing data from an XLSX file:

  • The parameters Worksheet and Header row are required.

  • All other parameters are optional. If you do not specify anything, all rows and columns containing data on the specified worksheet are imported.

  • When importing an XLSX file, a separate data source must be created for each worksheet to be imported.
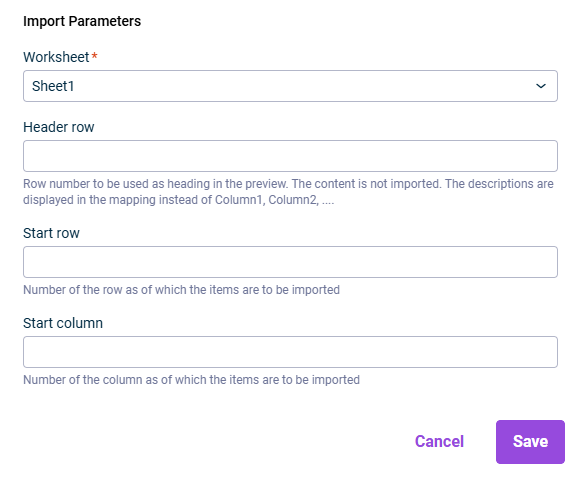
Shows the 'Import Parameters' area of a data source in Disclosure Management with the mandatory field 'Worksheet' (value 'Sheet1') and the fields 'Header row', 'Start row' and 'Start column'.
Parameters for Importing from an Excel File

No additional parameters are required when importing a CSV file.

When importing from a Lucanet database:

  • You can select all elements available in the Lucanet database from which you want to import.
  • If multiple selection is possible, check boxes for selecting the individual elements are displayed in the drop-down lists.
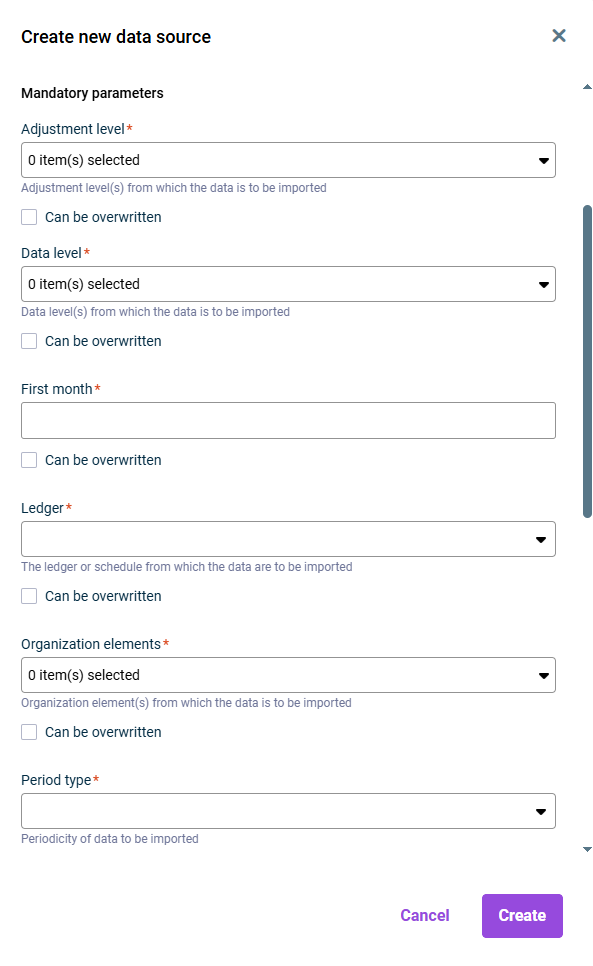
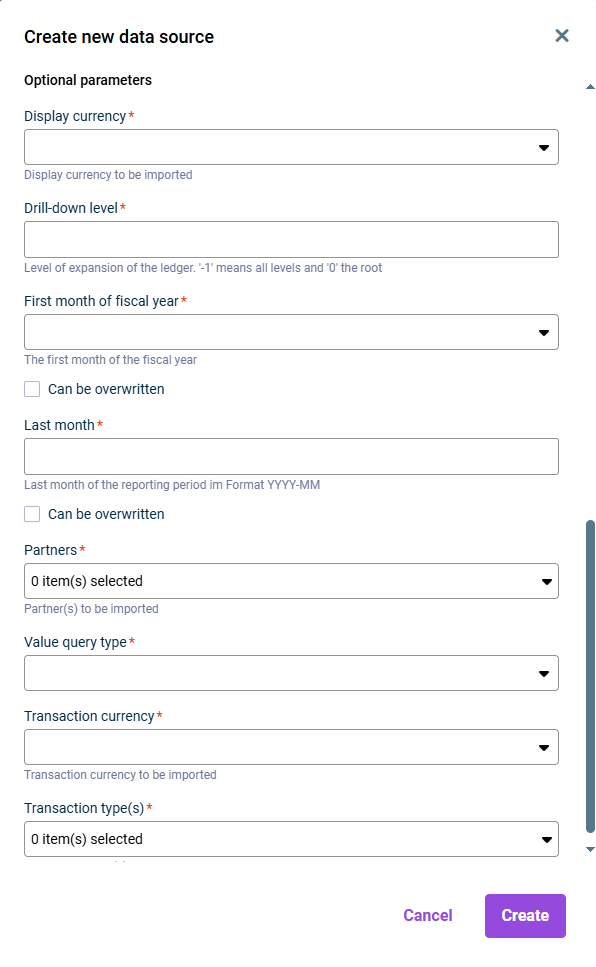
  • Select the Can be overwritten check box if the parameters you specify here can be overwritten by parameters you specify when performing the import. For additional information on parameterization when performing the import, see Configuring and Executing a Data Import.

All import parameters are described in the user interface.

Shows the 'Mandatory parameters' area of the 'Create new data source' dialog in Disclosure Management with the fields 'Adjustment level', 'Data level', 'First month', 'Ledger', 'Organization elements' and 'Period type', most of them with the option 'Can be overwritten'.
Mandatory parameters for importing from a Lucanet database
Shows the 'Optional parameters' area of the 'Create new data source' dialog in Disclosure Management with the fields 'Display currency', 'Drill-down level', 'First month of fiscal year', 'Last month', 'Partners', 'Value query type', 'Transaction currency' and 'Transaction type(s)'.
Optional parameters for importing from a Lucanet database
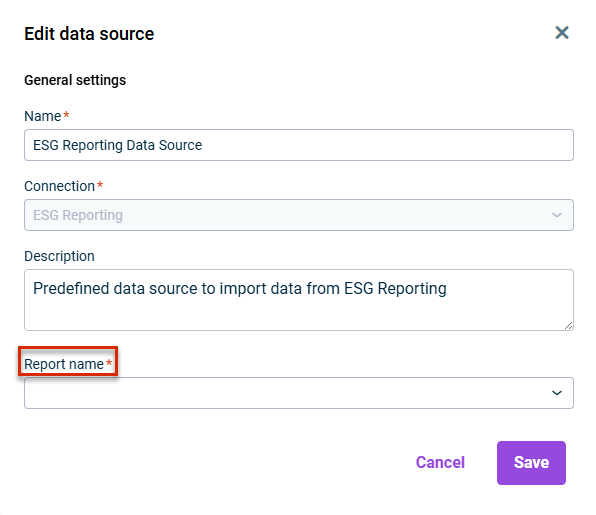
Shows the 'Edit data source' dialog in Disclosure Management for the data source 'ESG Reporting Data Source' with the connection 'ESG Reporting'. Highlighted in red is the mandatory field 'Report name'.
Import parameters for importing from Lucanet ESG Reporting
Description

Report name

Select the ESG report from which data is to be imported.

  • All reports that have been created in the Lucanet ESG Reporting solution and for which the data has already been aggregated are available for selection.

    For further information on data aggregation of an ESG report can be found in Aggregating Data chapter of the Lucanet ESG Reporting solution documentation.
  • The predefined default data source ESG Reporting Datasource is available in the overview of data sources and can be used by all users who have licensed Lucanet ESG Reporting (see section Default Data Source for Importing from Lucanet ESG Reporting)

Mappings of a data source are required for subsequent use of the imported data in Disclosure Management.

Mappings are used to define which columns of an imported Excel file contain which values. The columns are stored when programming an Excel file that is used in a report so that the correct data is inserted in the report. For additional information on programming the reporting data in an Excel file, see Inserting Report Values in MS Excel.

In addition, one or more transformations and/or aggregations can optionally be defined for each mapping (i.e. whether the data should be converted, enriched and/or summarized before import).

Several mappings can be defined for a data source and selected during the import process. For example, a mapping can be created for different periods or periodicities.

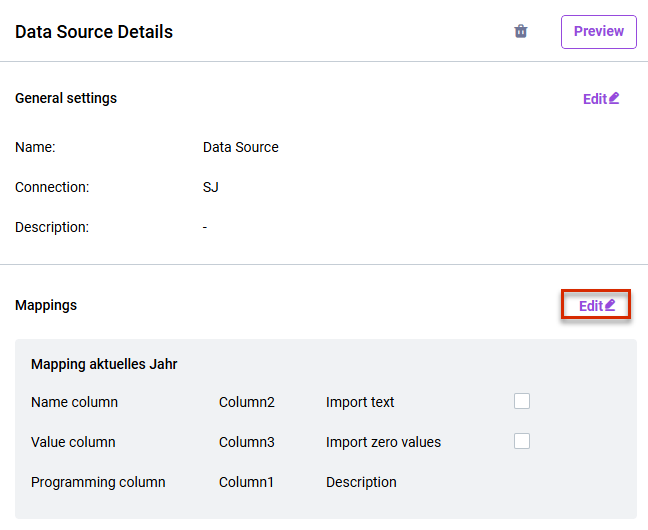
All existing mappings are shown in the Mappings area. By clicking Edit, you can create, edit or delete new mappings:

Shows the 'Data Source Details' in Disclosure Management with the 'General settings' area and the 'Mappings' area with the mapping 'Mapping aktuelles Jahr' ('Name column', 'Value column', 'Programming column', 'Import text', 'Import zero values'). Highlighted in red is the 'Edit' button in the 'Mappings' area.
Edit Mappings

To create a mapping for a data source in Disclosure Management:

1

In the detail view of the desired data source, click Edit in the Mappings area.

2

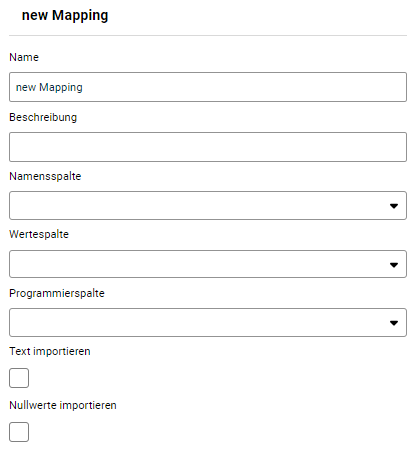
In the following view, click Add mapping. The following dialog is displayed:

Shows the mapping dialog 'new Mapping' in Disclosure Management in the German UI with the fields 'Name', 'Beschreibung', 'Namensspalte', 'Wertespalte' and 'Programmierspalte' and the options 'Text importieren' and 'Nullwerte importieren'.
Edit mapping
3

Then configure the fields for the mapping as follows:

The following table describes the fields of a mapping in Disclosure Management:

OptionDescription
NameName of the mapping.
DescriptionOptional description for the mapping
Name columnSelect the range in the data source that contains the names to be inserted in the name column of the programmed Excel file used in the report (e.g. the names of the accounts and/or items or the page of the balance sheet).
Value columnSelect the range in the data source that contains the values to be inserted into the value column of the programmed Excel file used in the report (e.g. values in a specific reporting year).
Programming columnSelect the range in the data source that contains unique identifiers to be inserted into programming column of the programmed Excel file used in the report (e.g. account numbers).
Import textActivate this option if cells with text are to be included in the import.
Import zero valuesActivate this option if cells with zero values are to be taken into account during the import.

You can use transformations in a Disclosure Management data source to specify whether source data should be converted or enriched before import. Transformations always create a new column in the imported data.

To create a transformation within a mapping in Disclosure Management:

1

In the detail view of the desired data source, click Edit.

2

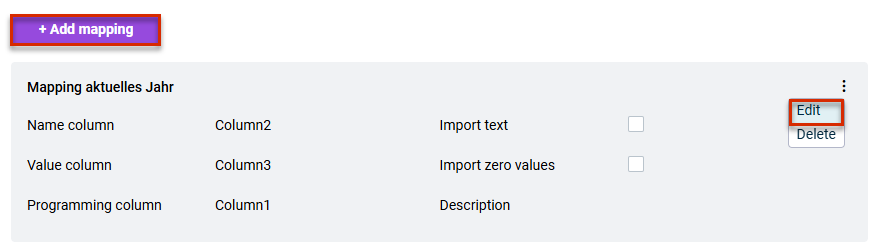
In the following view, click Add mapping or select Edit in the context menu of the three-dot iconThree dots icon of an existing mapping.

Shows the mappings of a data source in Disclosure Management with the mapping 'Mapping aktuelles Jahr' and the context menu of its three dots icon with the entries 'Edit' and 'Delete'. Highlighted in red are the '+ Add mapping' button and the 'Edit' entry.
Adding or editing a mapping
3

Edit the displayed fields.

An explanation of the fields is provided on the user interface.

In a text parameter, you can enter a document variable instead of a fixed value (see Using Document Variables in Text Parameters).

4

Click the Preview button and check the Imported data tab in the displayed window to determine whether the transformation provides the desired result.

The following transformation types are currently available in Disclosure Management:

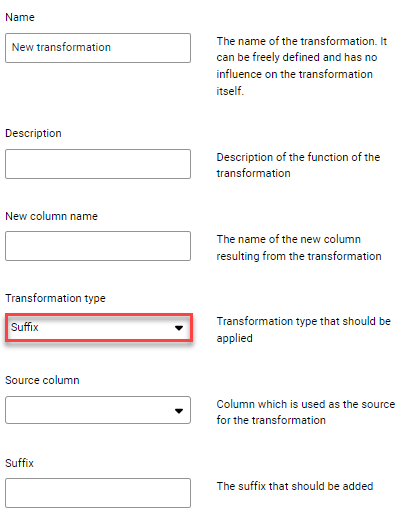
The Suffix transformation in Disclosure Management is used to append a definable text to a value and write it to a new column.

Instead of a fixed value, the Suffix parameter can take its value from a document variable (see Using Document Variables in Text Parameters).

Shows the fields of a transformation in Disclosure Management: 'Name' (value 'New transformation'), 'Description', 'New column name', 'Transformation type', 'Source column' and 'Suffix', each with an explanation. Highlighted in red is the transformation type 'Suffix'.
Configuration of the 'Suffix' transformation

Example

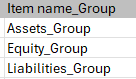
New column name: Item name_Group

Source column: Item name

Suffix: _Group

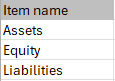
Column before transformation:

Shows an example column 'Item name' with the values 'Assets', 'Equity' and 'Liabilities' before the 'Suffix' transformation in Disclosure Management.
Column in Excel before transformation 'Suffix'

New column after transformation:

Shows the example column 'Item name_Group' with the values 'Assets_Group', 'Equity_Group' and 'Liabilities_Group' after the 'Suffix' transformation in Disclosure Management.
Column in Excel after transformation 'Suffix'

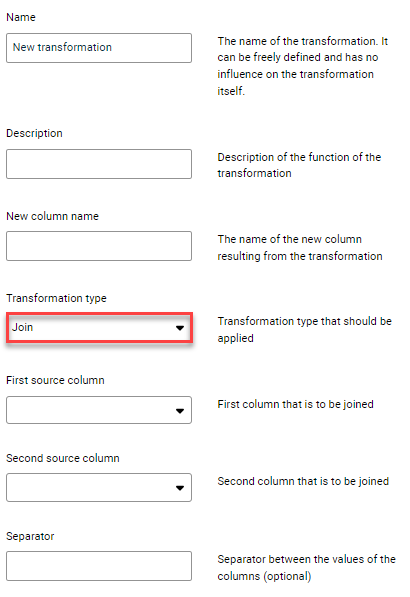
The transformation type Join in Disclosure Management is used to connect the values of two selectable columns and write them to a new column.

Shows the fields of a transformation in Disclosure Management: 'Name' (value 'New transformation'), 'Description', 'New column name', 'Transformation type', 'First source column', 'Second source column' and 'Separator', each with an explanation. Highlighted in red is the transformation type 'Join'.
Configuration of the 'Join' transformation

Example

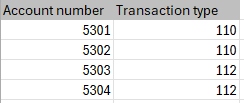
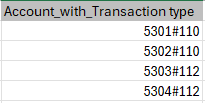
New column name: Account_with_Transaction_type

First source column: Account number

Second source column: Transaction type

Separator: #

Columns before transformation:

Shows the example columns 'Account number' (5301 to 5304) and 'Transaction type' (110 and 112) before the 'Join' transformation in Disclosure Management.
Columns in Excel before transformation 'Join'

New column after transformation:

Shows the example column 'Account_with_Transaction type' with the values '5301#110' to '5304#112' after the 'Join' transformation in Disclosure Management.
Column in Excel after transformation 'Join'

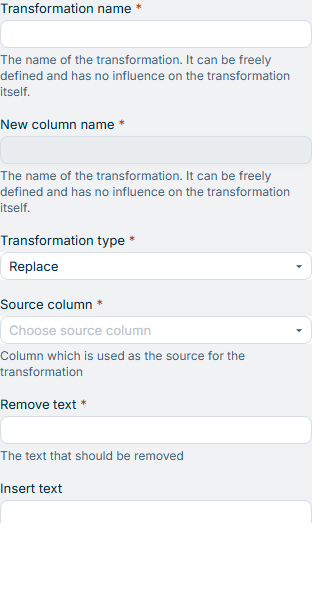
The transformation type Replace in Disclosure Management is used to replace text in a source column and write the result to a new column. All occurrences of the text entered in Remove text (mandatory) are replaced by the text entered in Insert text (optional). If you leave Insert text empty, the matched text is removed without replacement. You can use this, for example, to generate clean programming values from a raw source column.

Instead of a fixed value, the Remove text and Insert text parameters can take their values from a document variable (see Using Document Variables in Text Parameters).

Shows the fields of a transformation in Disclosure Management: 'Transformation name', 'New column name', 'Transformation type' with the value 'Replace', 'Source column', 'Remove text' and 'Insert text'.
Configuration of the 'Replace' transformation

Example

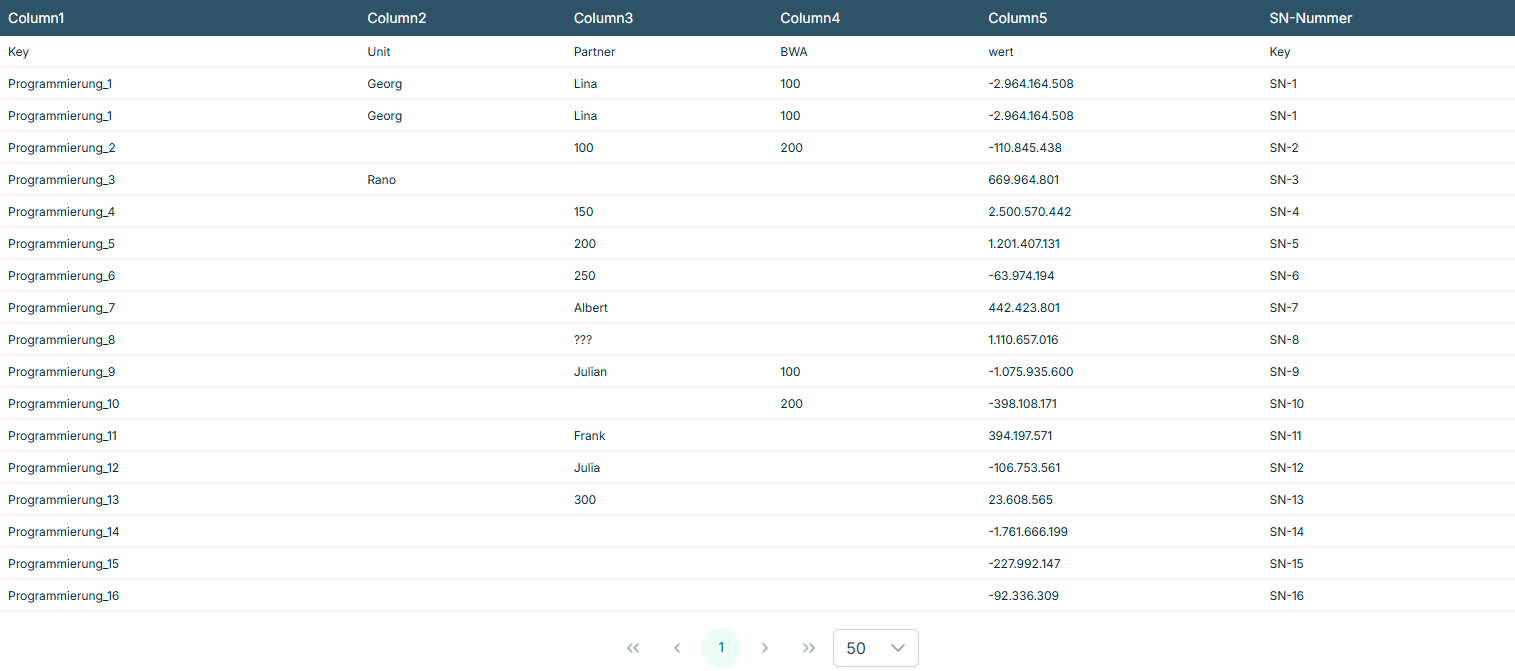
New column name: SN-Nummer

Source column: Column1

Remove text: Programmierung_

Insert text: SN-

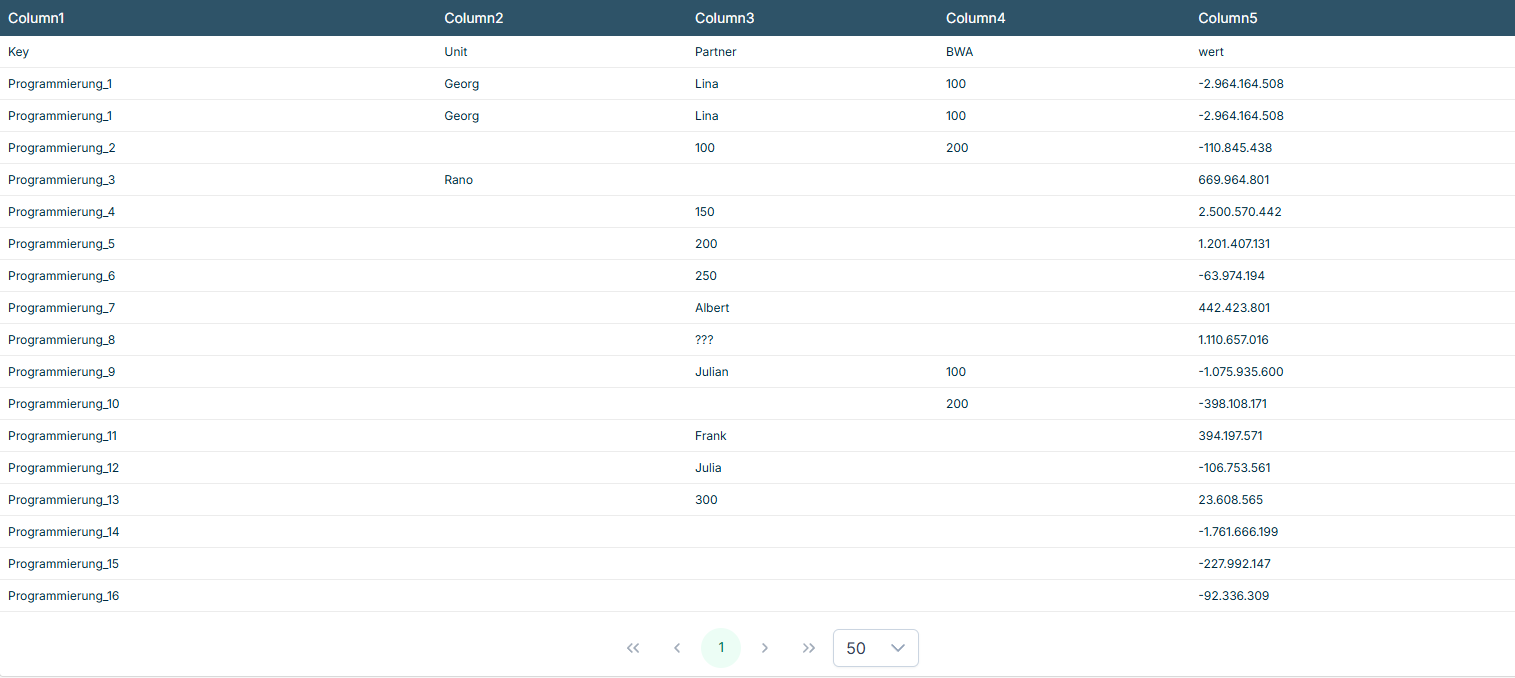
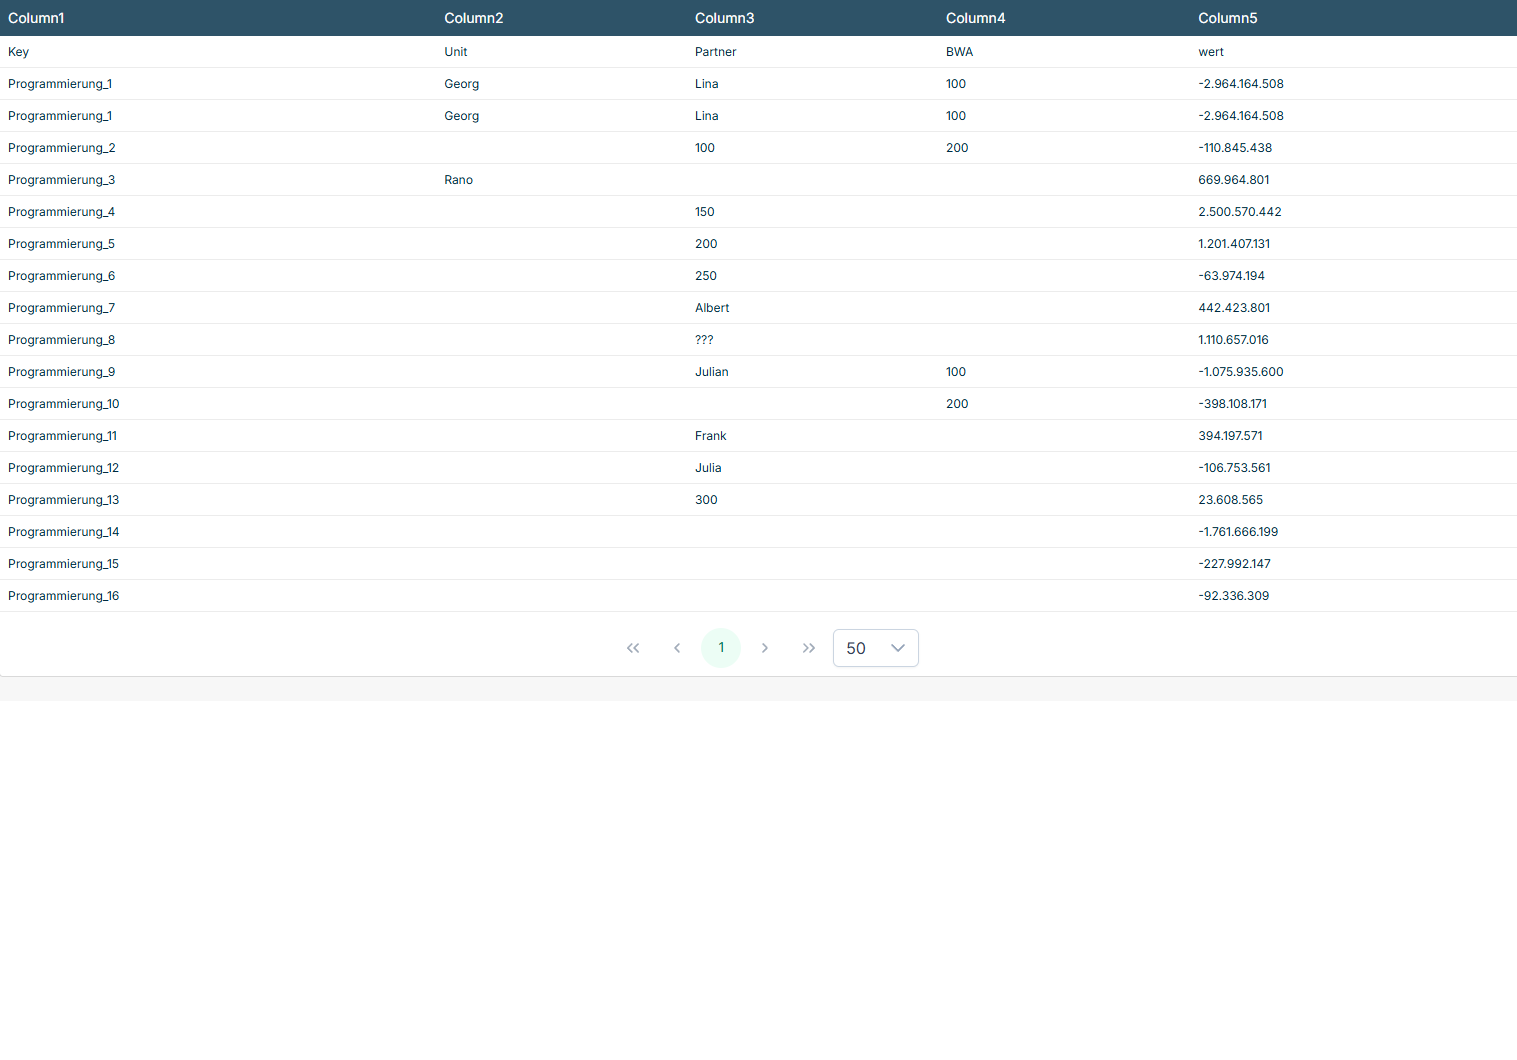
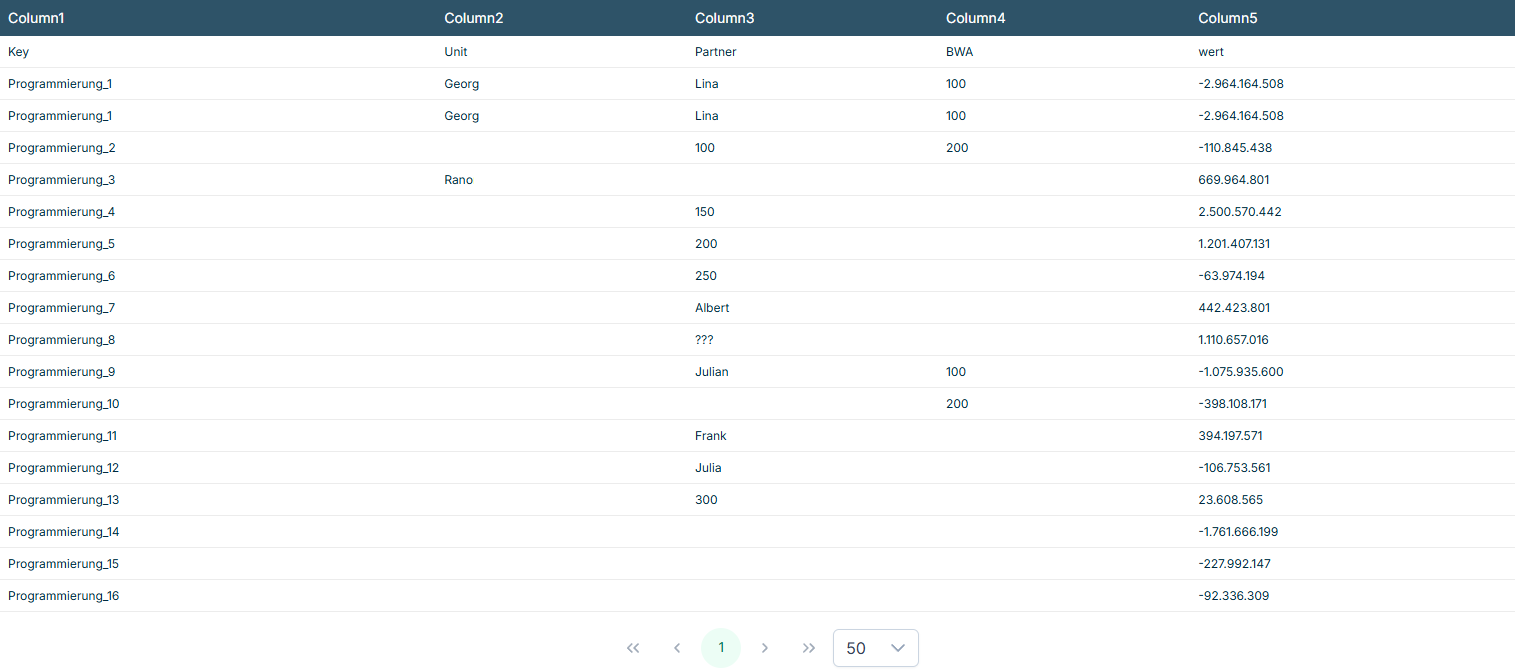
Source data before transformation:

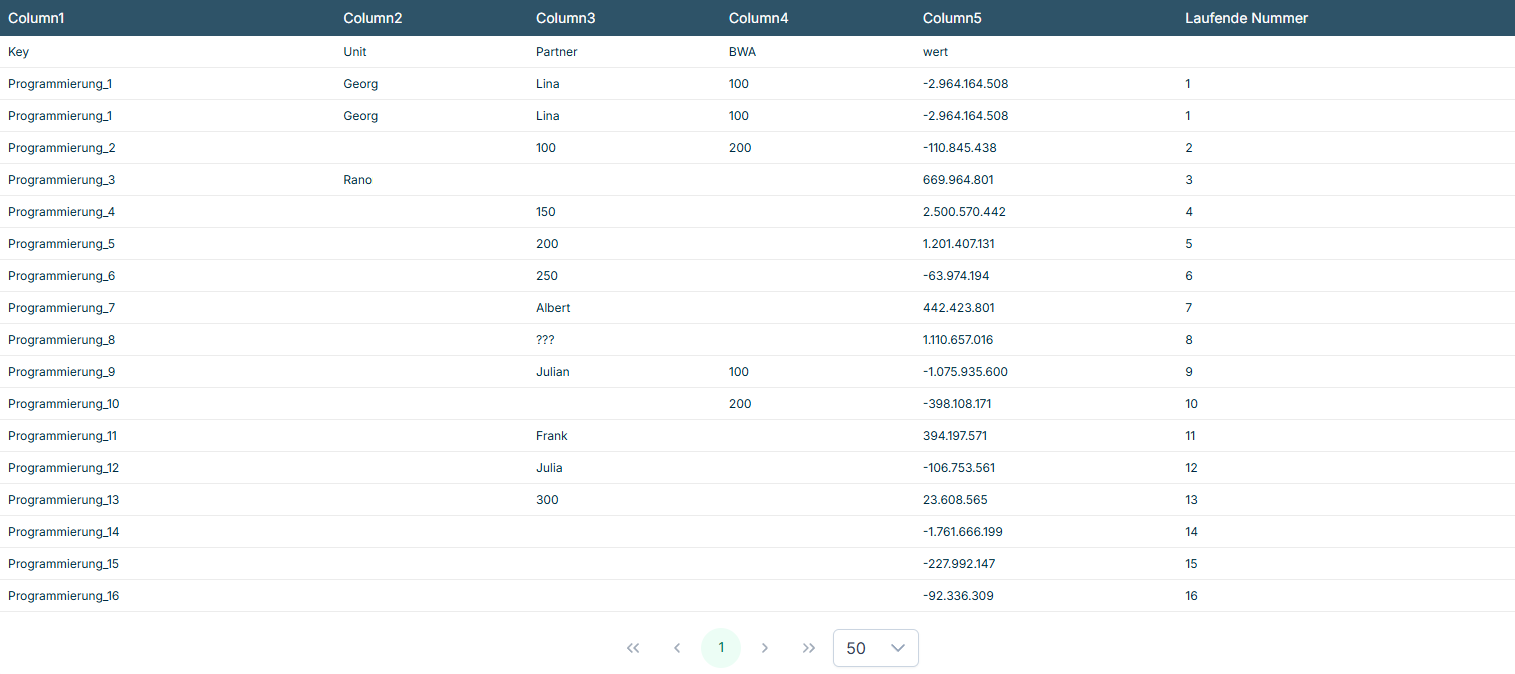
Shows example source data in the import preview of Disclosure Management with the columns 'Column1' to 'Column5', where 'Column1' contains the values 'Programmierung_1' to 'Programmierung_16', before the 'Replace' transformation.
Source data before transformation 'Replace'

New column after transformation:

Shows example processed data in the import preview of Disclosure Management with the new column 'SN-Nummer' and the values 'SN-1' to 'SN-16' next to the source column 'Column1' after the 'Replace' transformation.
Processed data after transformation 'Replace'

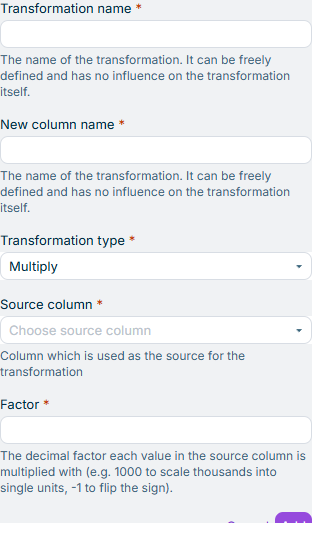
The transformation type Multiply in Disclosure Management is used to multiply each numeric value of a source column by a defined Factor and write the result to a new column. For example, you can use the factor 1000 to convert values reported in thousands into single units, or the factor -1 to flip the sign of a column. Non-numeric values are skipped (left empty in the result column) and empty cells remain empty. The result is formatted according to the same decimal and grouping rules as the Sum aggregation.

Shows the fields of a transformation in Disclosure Management: 'Transformation name', 'New column name', 'Transformation type' with the value 'Multiply', 'Source column' and 'Factor'.
Configuration of the 'Multiply' transformation

Example

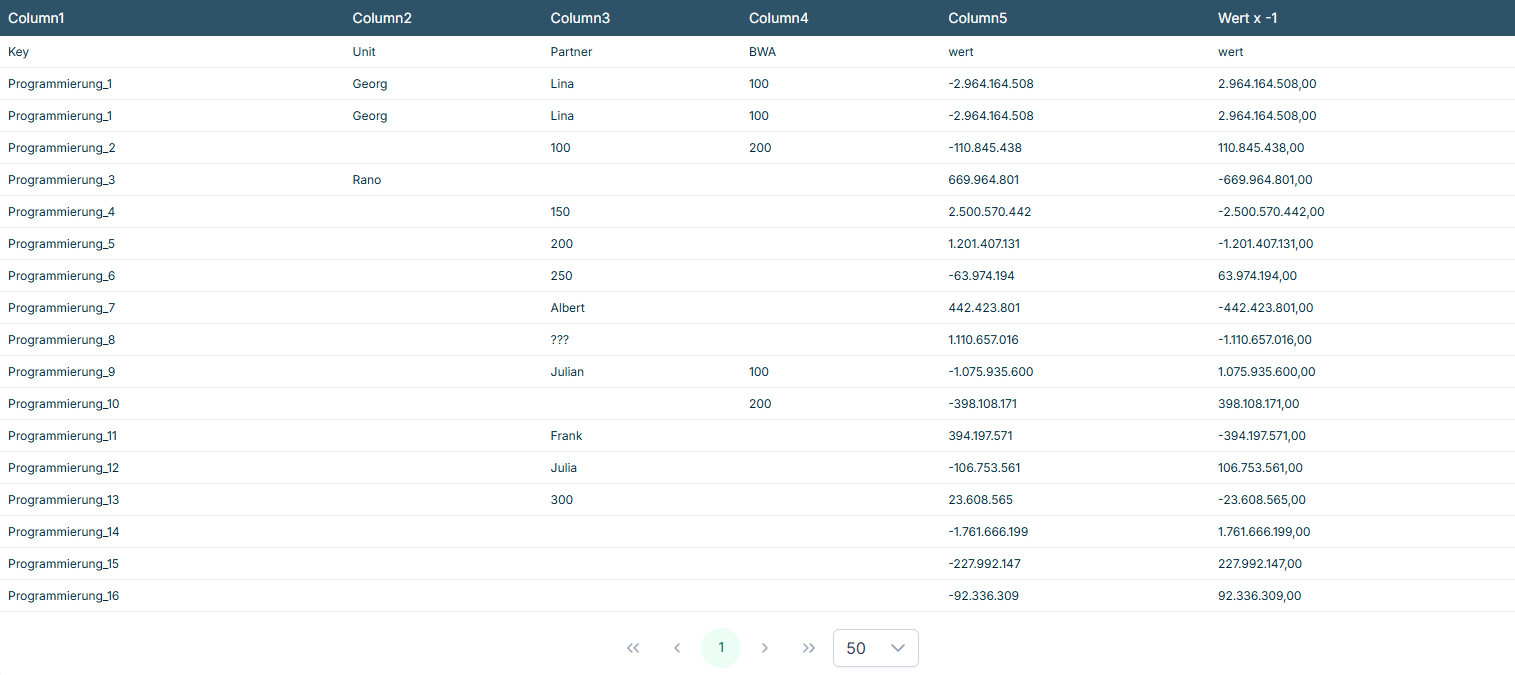
New column name: Wert x -1

Source column: Column5

Factor: -1

Source data before transformation:

Shows example source data in the import preview of Disclosure Management with the columns 'Column1' to 'Column5', where 'Column5' contains positive and negative values, before the 'Multiply' transformation.
Source data before transformation 'Multiply'

New column after transformation:

Shows example processed data in the import preview of Disclosure Management with the new column 'Wert x -1', which contains the values of 'Column5' with the sign flipped, after the 'Multiply' transformation.
Processed data after transformation 'Multiply'

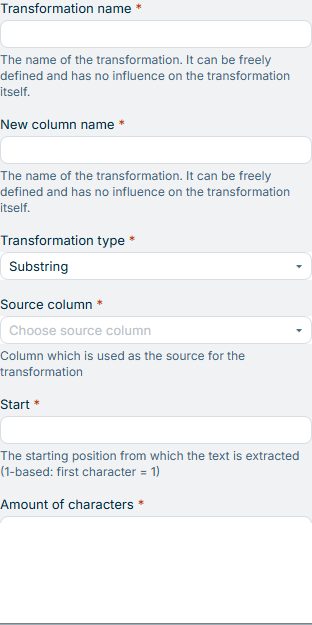
The transformation type Substring in Disclosure Management is used to extract a defined portion of a text value from a source column and write it to a new column. The extraction begins at the position entered in Start (1-based, so the first character is position 1) and returns the number of characters entered in Amount of characters. If the requested number of characters exceeds the remaining length of the value, the entire remaining text is returned. If the start position is beyond the length of the value, the result is empty. Both fields accept whole numbers greater than 0.

Shows the fields of a transformation in Disclosure Management: 'Transformation name', 'New column name', 'Transformation type' with the value 'Substring', 'Source column', 'Start' and 'Amount of characters'.
Configuration of the 'Substring' transformation

Example

New column name: Laufende Nummer

Source column: Column1

Start: 16

Amount of characters: 5

Source data before transformation:

Shows example source data in the import preview of Disclosure Management with the columns 'Column1' to 'Column5', where 'Column1' contains the values 'Programmierung_1' to 'Programmierung_16', before the 'Substring' transformation.
Source data before transformation 'Substring'

New column after transformation:

Shows example processed data in the import preview of Disclosure Management with the new column 'Laufende Nummer' and the values 1 to 16 extracted from 'Column1' after the 'Substring' transformation.
Processed data after transformation 'Substring'

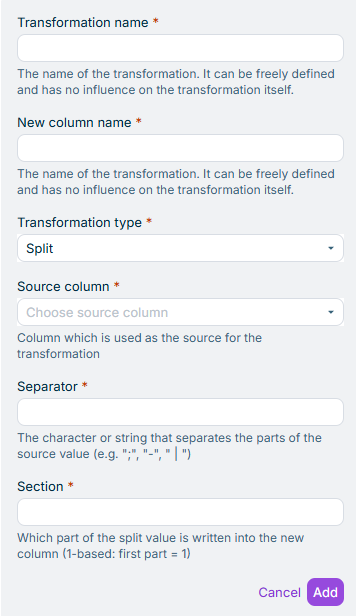
The transformation type Split in Disclosure Management is used to split a text value in a source column into parts using a defined separator and write the part at a specified index into a new column. Use this transformation to extract a specific segment from a composite key or delimited value – for example, to read the country code out of a value such as "Berlin;DE;10115".

After selecting Split as the transformation type in Disclosure Management, the following additional fields are displayed:

FieldDescription
SeparatorThe character or string that separates the parts of the source value (for example ";", "-", "|"). Accepts any non-empty string, including special characters and whitespace.
SectionWhich part of the split value is written into the new column (1-based: first part = 1). Accepts only integers greater than 0.
  • Each Split transformation produces exactly one new column. To extract multiple parts from the same source value, add multiple Split transformations.
  • If the source value does not contain the separator, the entire value is treated as part 1; Section 2 or higher returns an empty string.
  • If the Section index exceeds the number of parts, the new column receives an empty string – no error is raised.
  • Leading and trailing whitespace within split parts is preserved as-is.
Shows the fields of a transformation in Disclosure Management: 'Transformation name', 'New column name', 'Transformation type' with the value 'Split', 'Source column', 'Separator' and 'Section', and the buttons 'Cancel' and 'Add'.
Configuration of the 'Split' transformation

Example

New column name: Country code

Source column: Location

Separator: ;

Section: 2

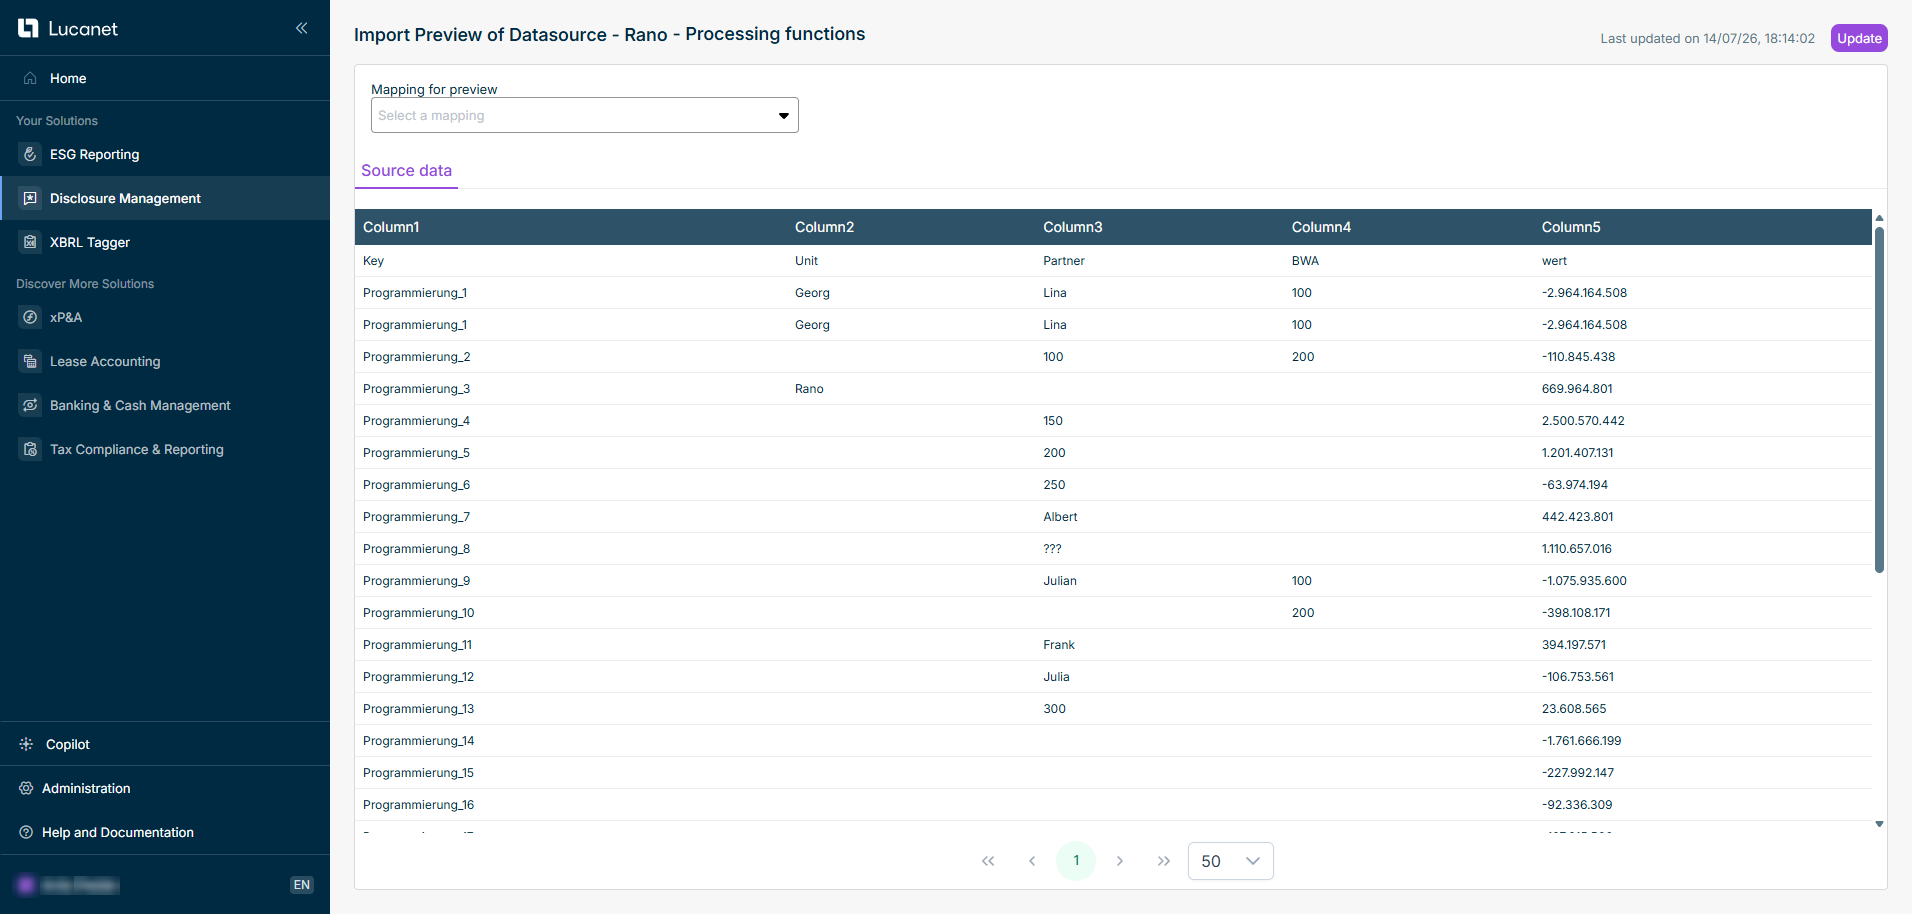
Source data before transformation:

Shows the 'Source data' tab of the 'Import Preview of Datasource - Rano - Processing functions' window in Disclosure Management with the columns 'Column1' to 'Column5', where 'Column1' contains the values 'Programmierung_1' to 'Programmierung_16'.
Source data before transformation 'Split'

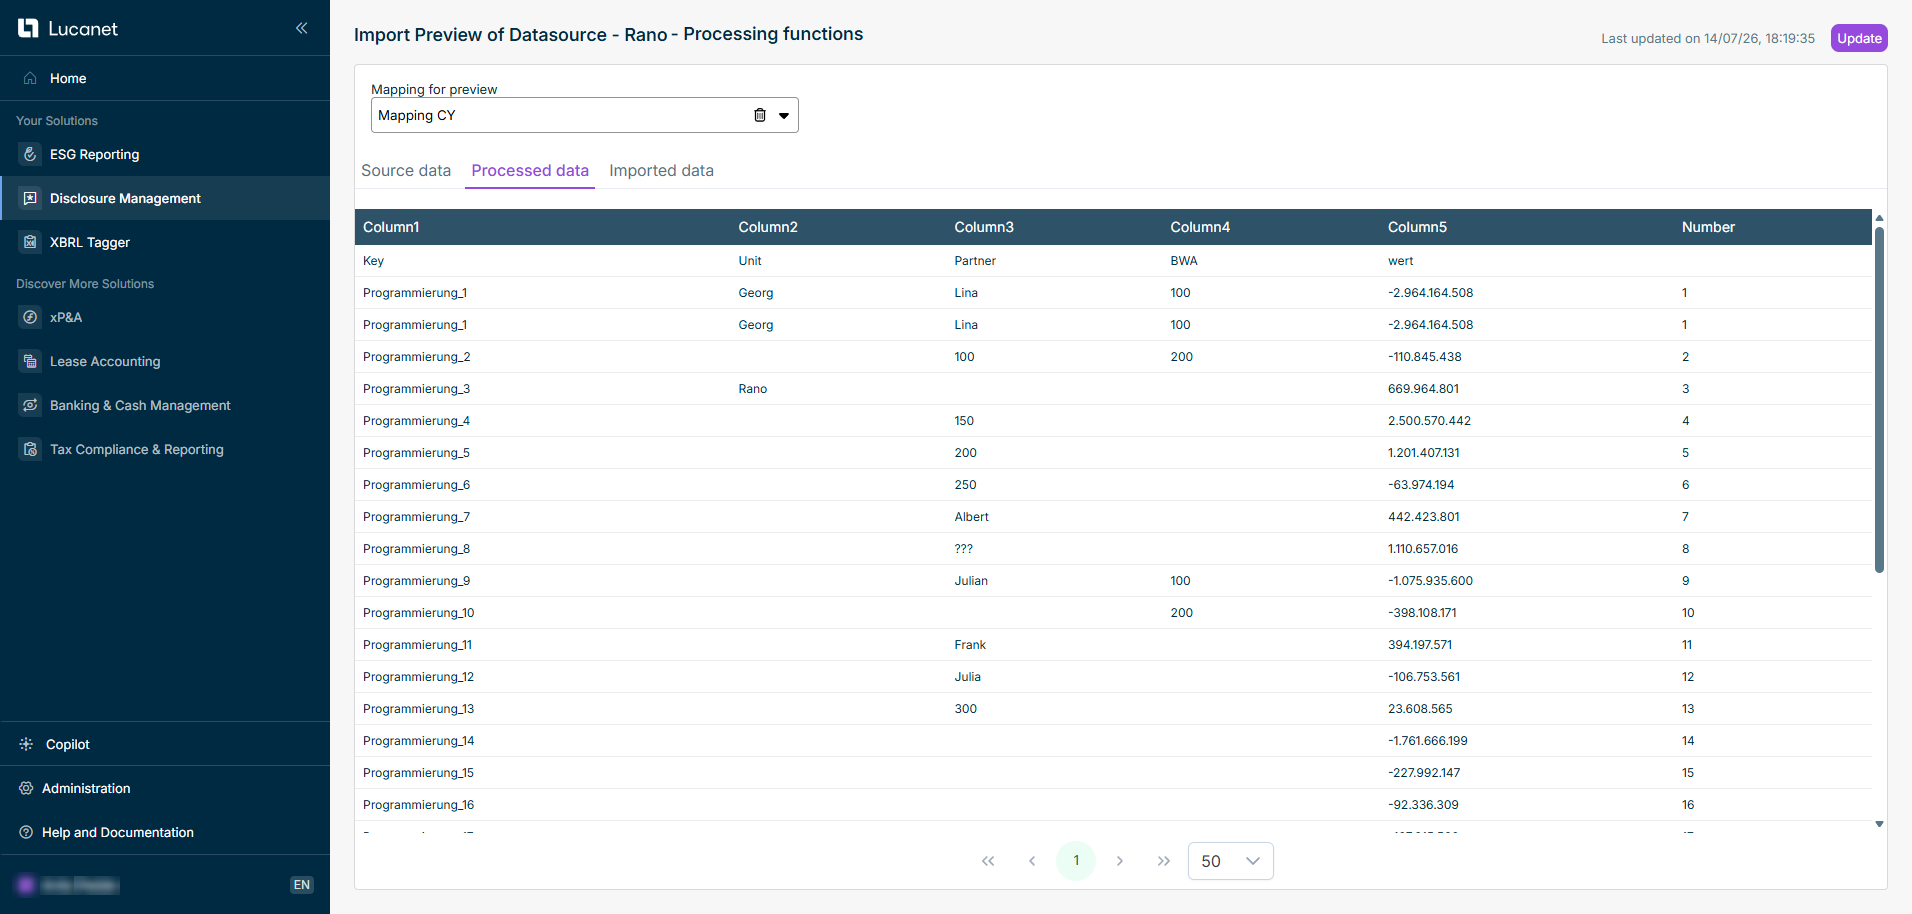
New column after transformation:

Shows the 'Processed data' tab of the 'Import Preview of Datasource - Rano - Processing functions' window in Disclosure Management with the mapping 'Mapping CY' and the new column 'Number' with the values 1 to 16.
Processed data after transformation 'Split'

The transformation type Take over in Disclosure Management processes a source column row by row, top to bottom, and writes a value into a new column for every row:

  • If the source cell in the current row is non-empty, that value is copied unchanged into the new column.
  • If the source cell in the current row is empty, the new column receives the value from the most recent non-empty source cell above.

Use this transformation to flatten grouped or header-style source data – for example, when a parent account name appears only once at the top of a group and the rows below are left blank.

  • If the first rows have no non-empty source value above them, the new column remains empty for those rows.
  • A value counts as empty when it is null, an empty string, or contains only whitespace.
  • The source column itself is not modified; the filled values are written exclusively into the new column.
  • The fill value updates every time a non-empty source cell is encountered. The row order at the time of execution depends on any preceding sort or filter processings.
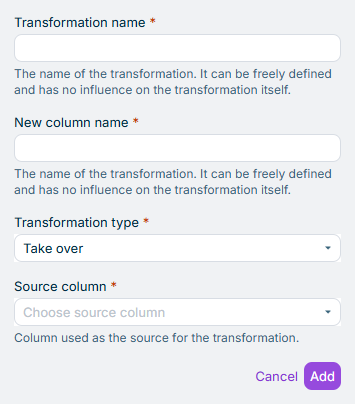
Shows the fields of a transformation in Disclosure Management: 'Transformation name', 'New column name', 'Transformation type' with the value 'Take over' and 'Source column', and the buttons 'Cancel' and 'Add'.
Configuration of the 'Take over' transformation

Example

New column name: Account group

Source column: Group header

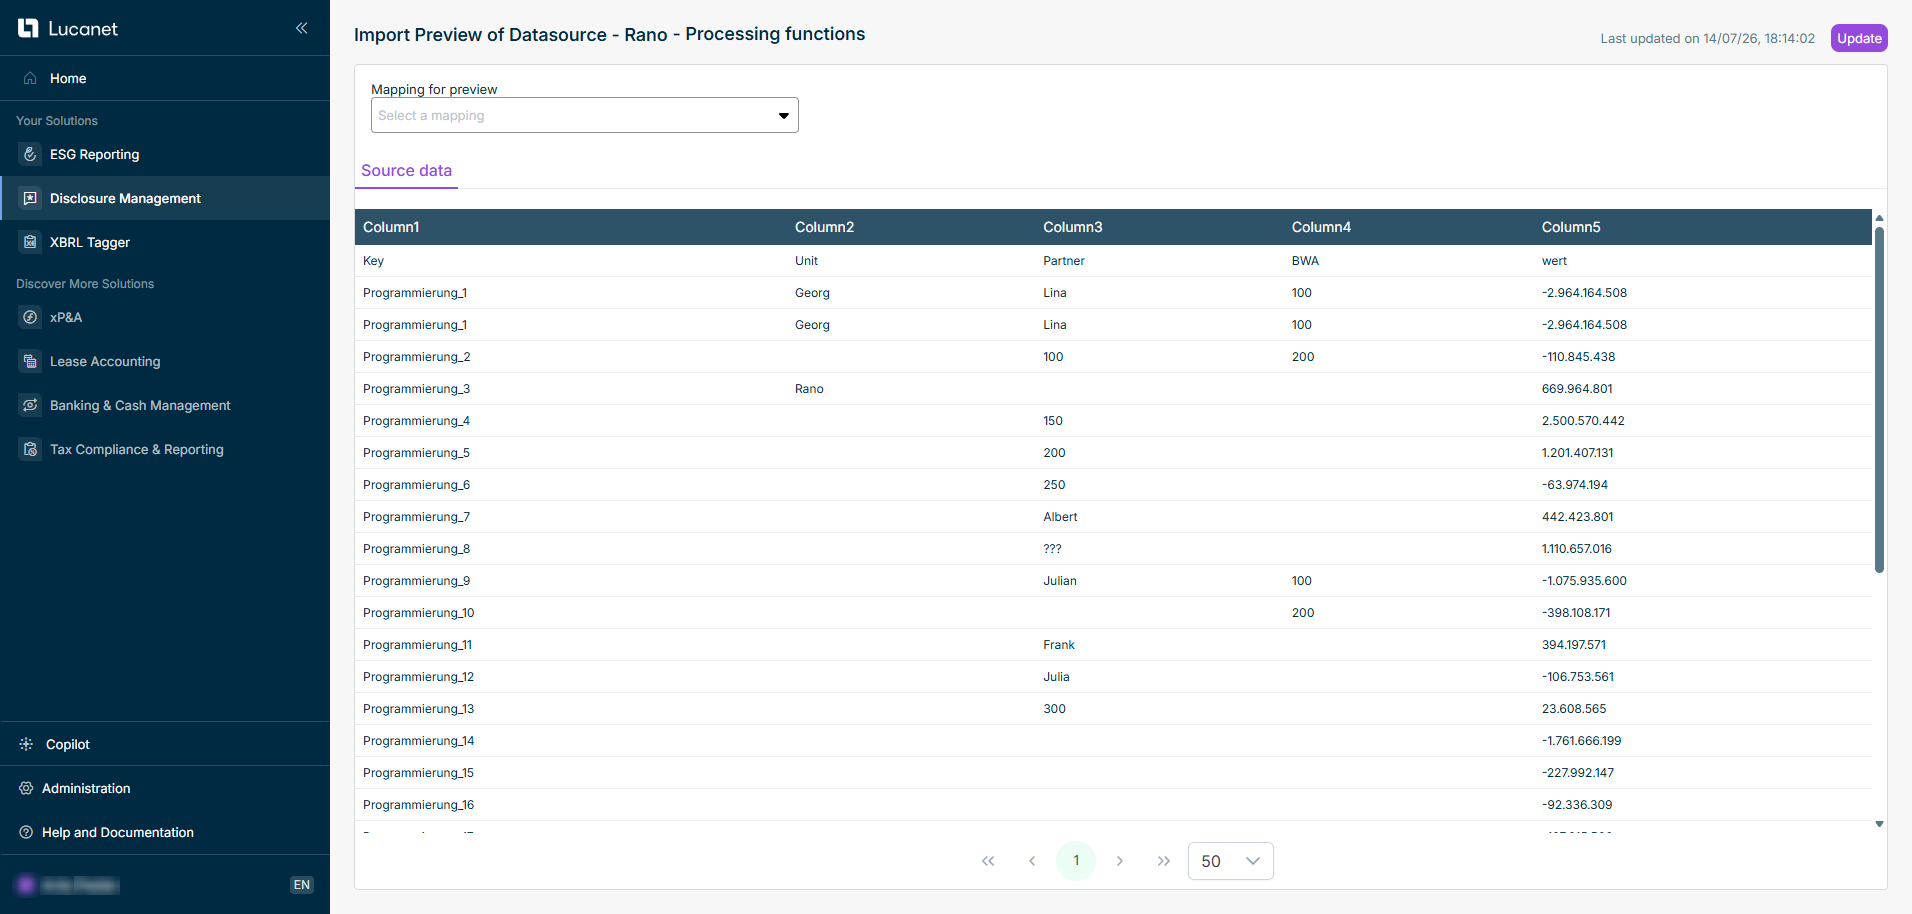
Source data before transformation:

Shows the 'Source data' tab of the 'Import Preview of Datasource - Rano - Processing functions' window in Disclosure Management with the columns 'Column1' to 'Column5', where 'Column2' contains the values 'Georg' and 'Rano' in some rows and empty cells in the rows below.
Source data before transformation 'Take over'

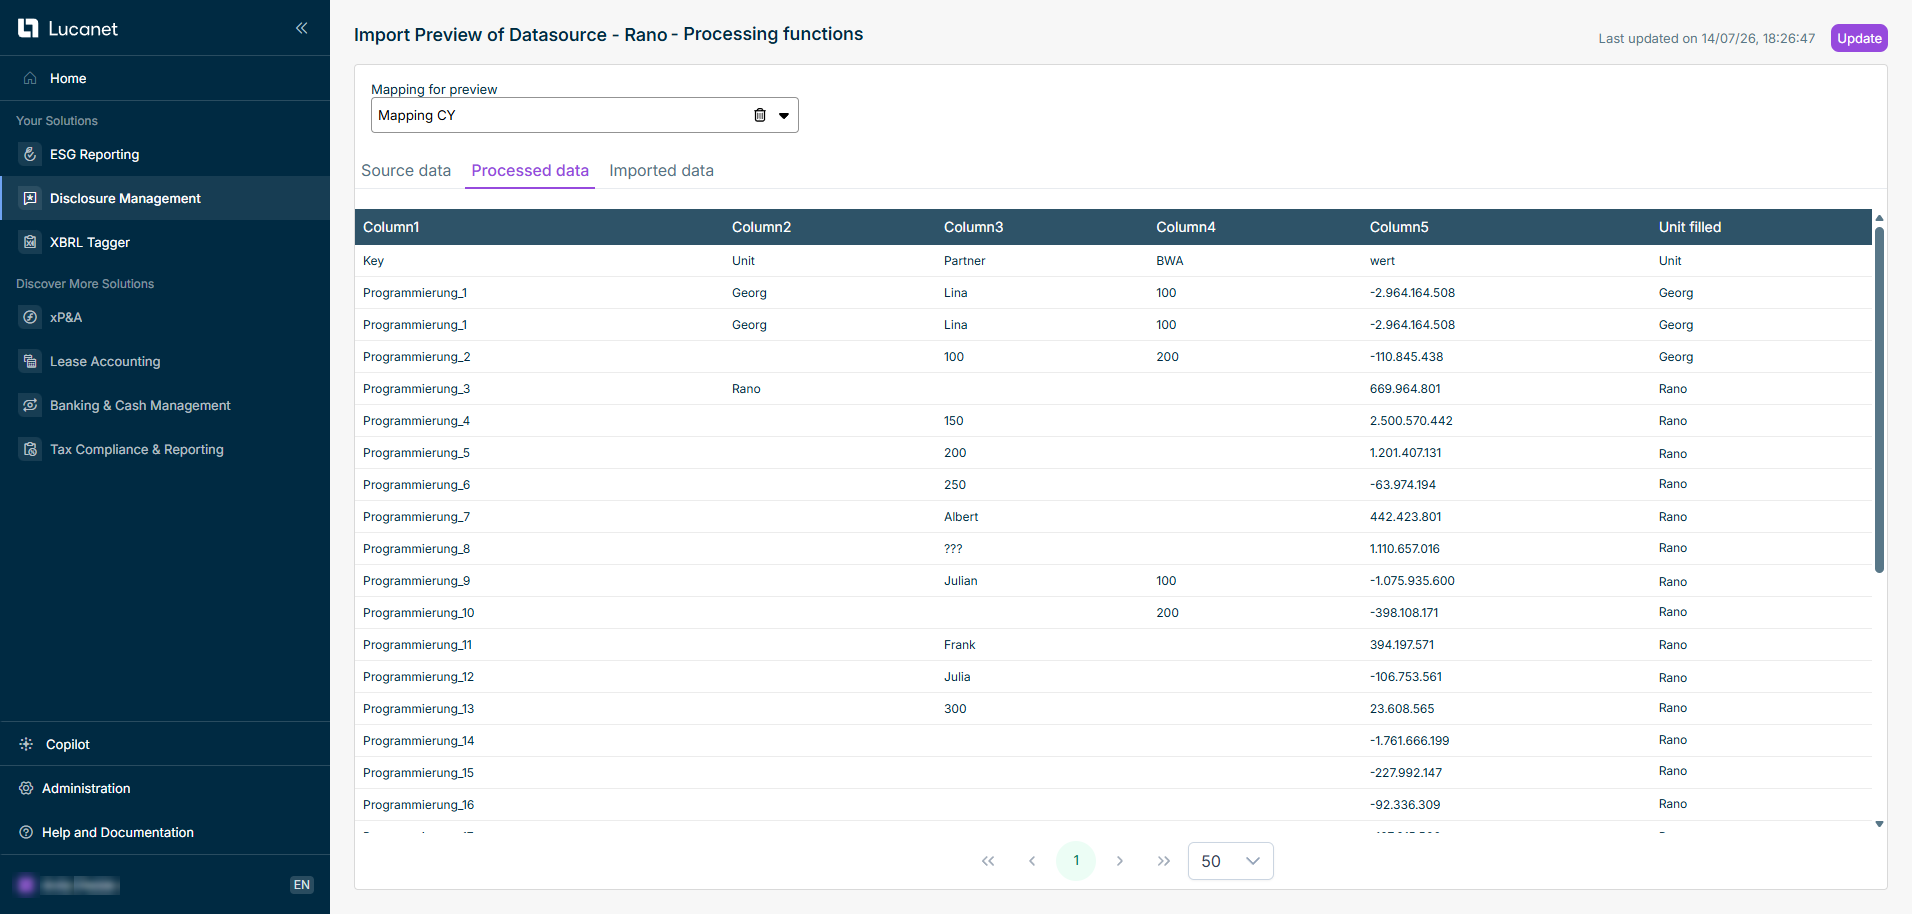
New column after transformation:

Shows the 'Processed data' tab of the 'Import Preview of Datasource - Rano - Processing functions' window in Disclosure Management with the mapping 'Mapping CY' and the new column 'Unit filled', in which the values 'Georg' and 'Rano' from 'Column2' are filled down into the empty rows below.
Processed data after transformation 'Take over'

You can use aggregations in a Disclosure Management data source to specify whether source data should be aggregated (i.e. summarized) before import.

To create an aggregation within a mapping in Disclosure Management:

1

In the detail view of the desired data source, click Edit.

2

In the following view, click Add mapping or select Edit in the context menu of the three-dot iconThree dots icon of an existing mapping.

Shows the mappings of a data source in Disclosure Management with the mapping 'Mapping aktuelles Jahr' and the context menu of its three dots icon with the entries 'Edit' and 'Delete'. Highlighted in red are the '+ Add mapping' button and the 'Edit' entry.
Adding or editing a mapping
3

Edit the displayed fields.

An explanation of the fields is provided on the user interface.

In a text parameter, you can enter a document variable instead of a fixed value (see Using Document Variables in Text Parameters).

4

Click the Preview button and check the Imported data tab in the displayed window to determine whether the aggregation provides the desired result.

The following aggregation types are currently available in Disclosure Management:

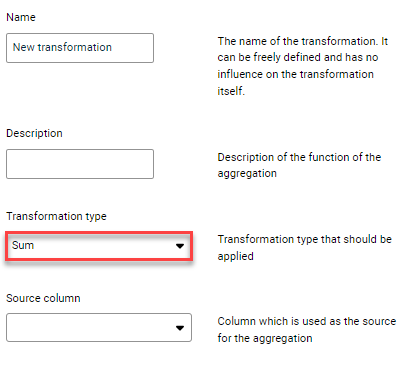
You can use the Sum aggregation in Disclosure Management to total all numerical values in the value column – grouped according to the source column to which the total function is applied.

Shows the fields of an aggregation in Disclosure Management: 'Name' (value 'New transformation'), 'Description', 'Transformation type' and 'Source column', each with an explanation. Highlighted in red is the type 'Sum'.
Configuration of the aggregation of type 'Sum'

Example

Source column: Column2

Columns before aggregation:

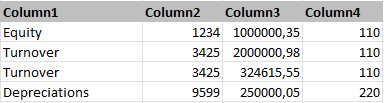
Shows example columns 'Column1' to 'Column4' with the rows 'Equity', two rows 'Turnover' (both 3425 in 'Column2') and 'Depreciations' before the 'Sum' aggregation in Disclosure Management.
Column in Excel before aggregation 'Sum'

Columns after aggregation:

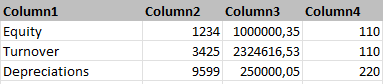
Shows the example columns 'Column1' to 'Column4' after the 'Sum' aggregation in Disclosure Management, with the two 'Turnover' rows combined into one row with the summed value 2324616,53.
Column in Excel after aggregation 'Sum'

You can use the Filter aggregation type in Disclosure Management to import only values that match the defined filter condition.

Instead of a fixed value, the Filter parameter can take its value from a document variable (see Using Document Variables in Text Parameters).

The condition must be entered manually into the Filter field. The filter value or text must be placed in double inverted commas.

The following arithmetical and logical operators are available for defining the filter condition:

Arithmetical operators for text filters:

  • '=' imports all rows that match the specified filter text exactly.
  • < imports all rows whose text comes after the specified filter text in their relative position in the alphabetical sort order.
  • <= imports all rows whose text in their relative position in the alphabetical sort order is in the same position or after the specified filter text.
  • > imports all rows whose text comes before the specified filter text in their relative position in the alphabetical sort order.
  • >= imports all rows whose text in their relative position in the alphabetical sort order is in the same position or before the specified filter text.
  • <> displays all rows that do not match the specified filter text exactly.
  • contains displays all rows that contain the specified filter text at any location.
  • notContains displays all rows that do not contain the specified filter text.

Arithmetical operators for number filters:

  • < displays all rows with a value greater than the specified number. If the value in a row is a text, it is not taken into account.
  • <= displays all rows with a value greater than or equal to the specified number. If the value in a row is a text, it is not taken into account.
  • > displays all rows with a value that is less than the specified number. If the value in a row is a text, it is not taken into account.
  • >= displays all rows with a value less than or equal to the specified number. If the value in a row is a text, it is not taken into account.
  • <> displays all rows that do not match the specified filter text exactly
  • contains displays all rows that contain the specified filter value at any location
  • notContains displays all rows that do not contain the specified filter value

Logical operators:

Filter conditions can be linked with and and or.

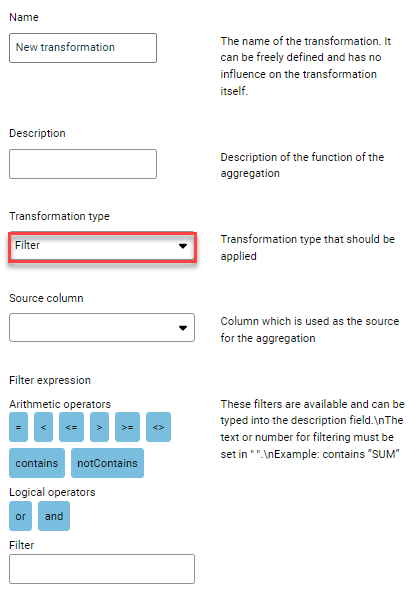
Shows the fields of an aggregation in Disclosure Management: 'Name', 'Description', 'Transformation type' and 'Source column', and the area 'Filter expression' with the 'Arithmetic operators' (=, <, <=, >, >=, <>, contains, notContains), the 'Logical operators' (or, and) and the field 'Filter'. Highlighted in red is the type 'Filter'.
Configuration of the aggregation of type 'Filter'

Example

Source column: Transaction type

Filter expression: contains "110"

Column before aggregation:

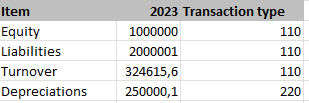
Shows example columns 'Item', '2023' and 'Transaction type' with the rows 'Equity', 'Liabilities' and 'Turnover' (transaction type 110) and 'Depreciations' (transaction type 220) before the 'Filter' aggregation in Disclosure Management.
Column in Excel before aggregation 'Filter'

Column after aggregation:

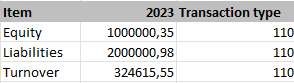
Shows the example columns after the 'Filter' aggregation in Disclosure Management with only the rows 'Equity', 'Liabilities' and 'Turnover', which have the transaction type 110.
Column in Excel after aggregation 'Filter'

The Filter not empty aggregation type in Disclosure Management removes every row whose value in the selected source column is empty. A value counts as empty when it is null, an empty string, or contains only whitespace (spaces, tabs). Rows with a non-whitespace value in the source column are kept unchanged. Other columns are not modified.

Filter not empty does not create a new column – the New column name field is not displayed for this aggregation type.

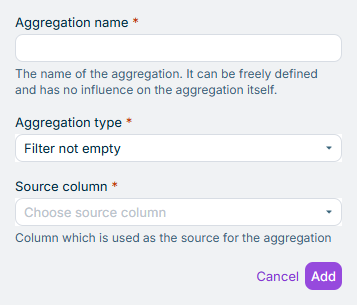
Shows the fields of an aggregation in Disclosure Management: 'Aggregation name', 'Aggregation type' with the value 'Filter not empty' and 'Source column', and the buttons 'Cancel' and 'Add'.
Configuration of the aggregation 'Filter not empty'

Example

Aggregation name: Remove empty keys

Source column: Programming key

Rows before aggregation:

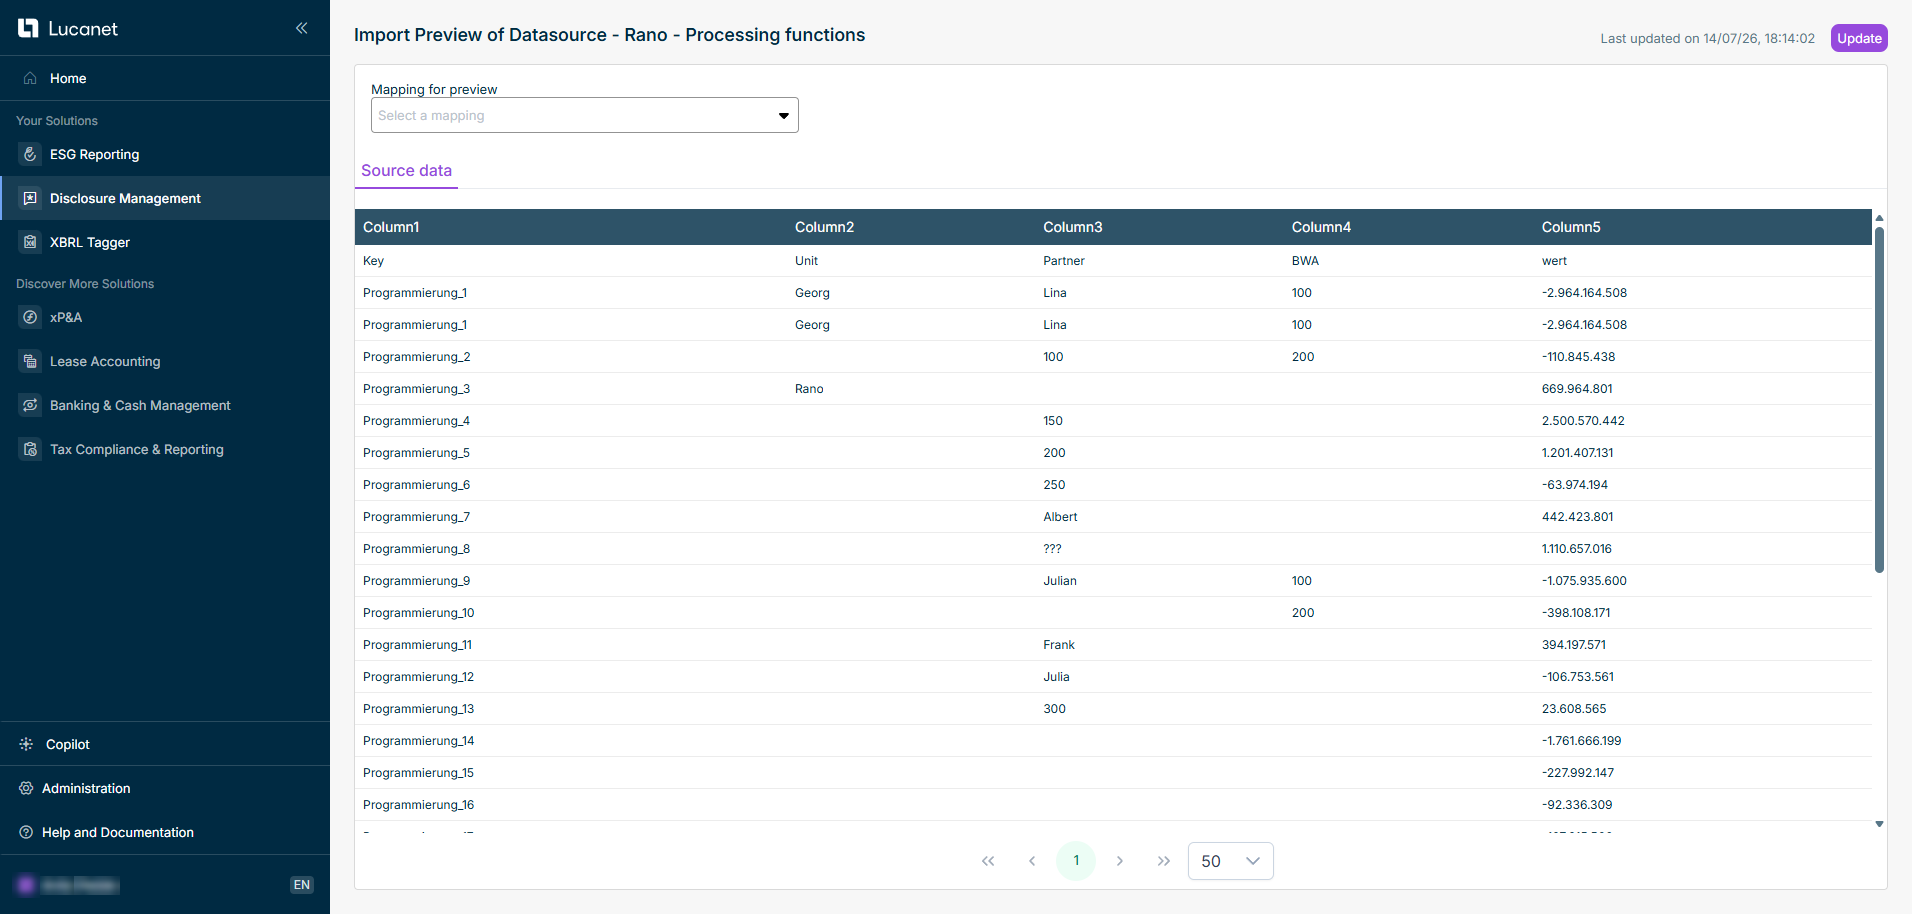
Shows the 'Source data' tab of the 'Import Preview of Datasource - Rano - Processing functions' window in Disclosure Management with the columns 'Column1' to 'Column5', where 'Column2' has values only in some rows.
Source data before aggregation 'Filter not empty'

Rows after aggregation:

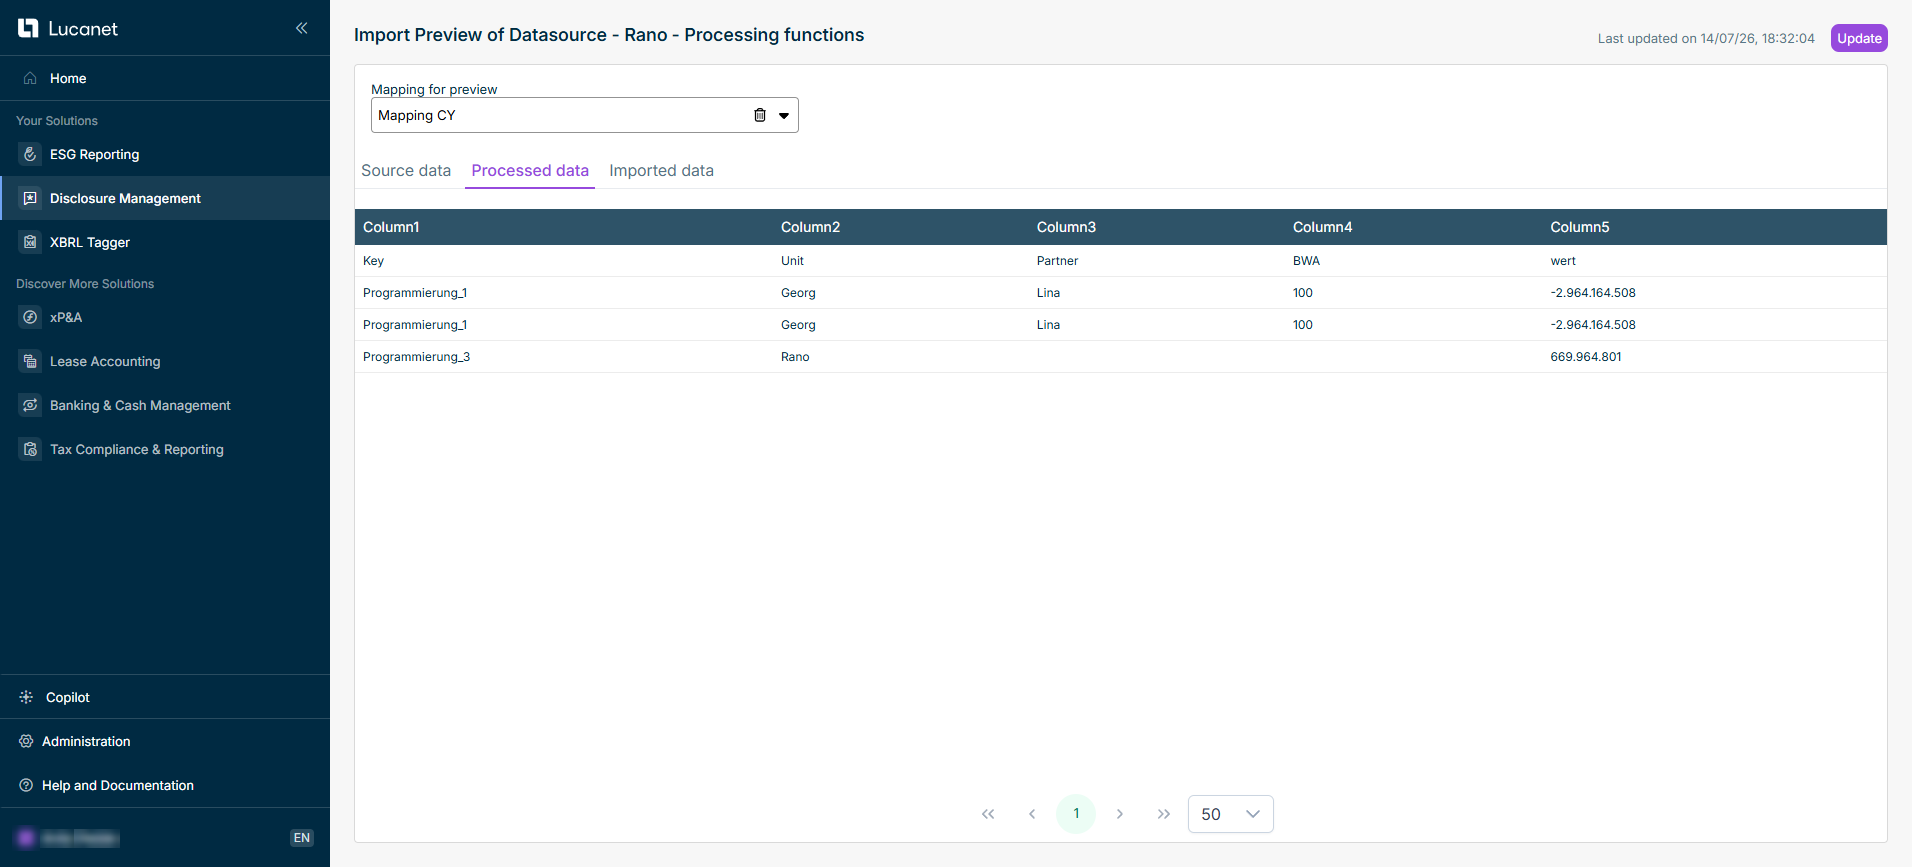
Shows the 'Processed data' tab of the 'Import Preview of Datasource - Rano - Processing functions' window in Disclosure Management with the mapping 'Mapping CY' and only the rows that have a value in 'Column2' ('Key', two rows 'Programmierung_1' and 'Programmierung_3').
Processed data after aggregation 'Filter not empty'

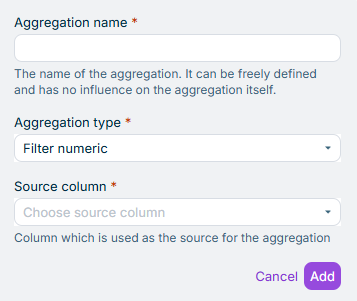
The Filter numeric aggregation type in Disclosure Management keeps only rows whose value in the selected source column is numeric. A value counts as numeric when it can be parsed as a decimal number according to the connector's number format settings (consistent with the Sum aggregation). Negative values and decimal values count as numeric. Empty cells, text values, and values containing non-numeric characters are not counted as numeric and the corresponding rows are removed. Other columns are not modified.

Filter numeric does not create a new column – the New column name field is not displayed for this aggregation type.

Shows the fields of an aggregation in Disclosure Management: 'Aggregation name', 'Aggregation type' with the value 'Filter numeric' and 'Source column', and the buttons 'Cancel' and 'Add'.
Configuration of the aggregation of type 'Filter numeric'

Example

Aggregation name: Keep numeric amounts only

Source column: Amount

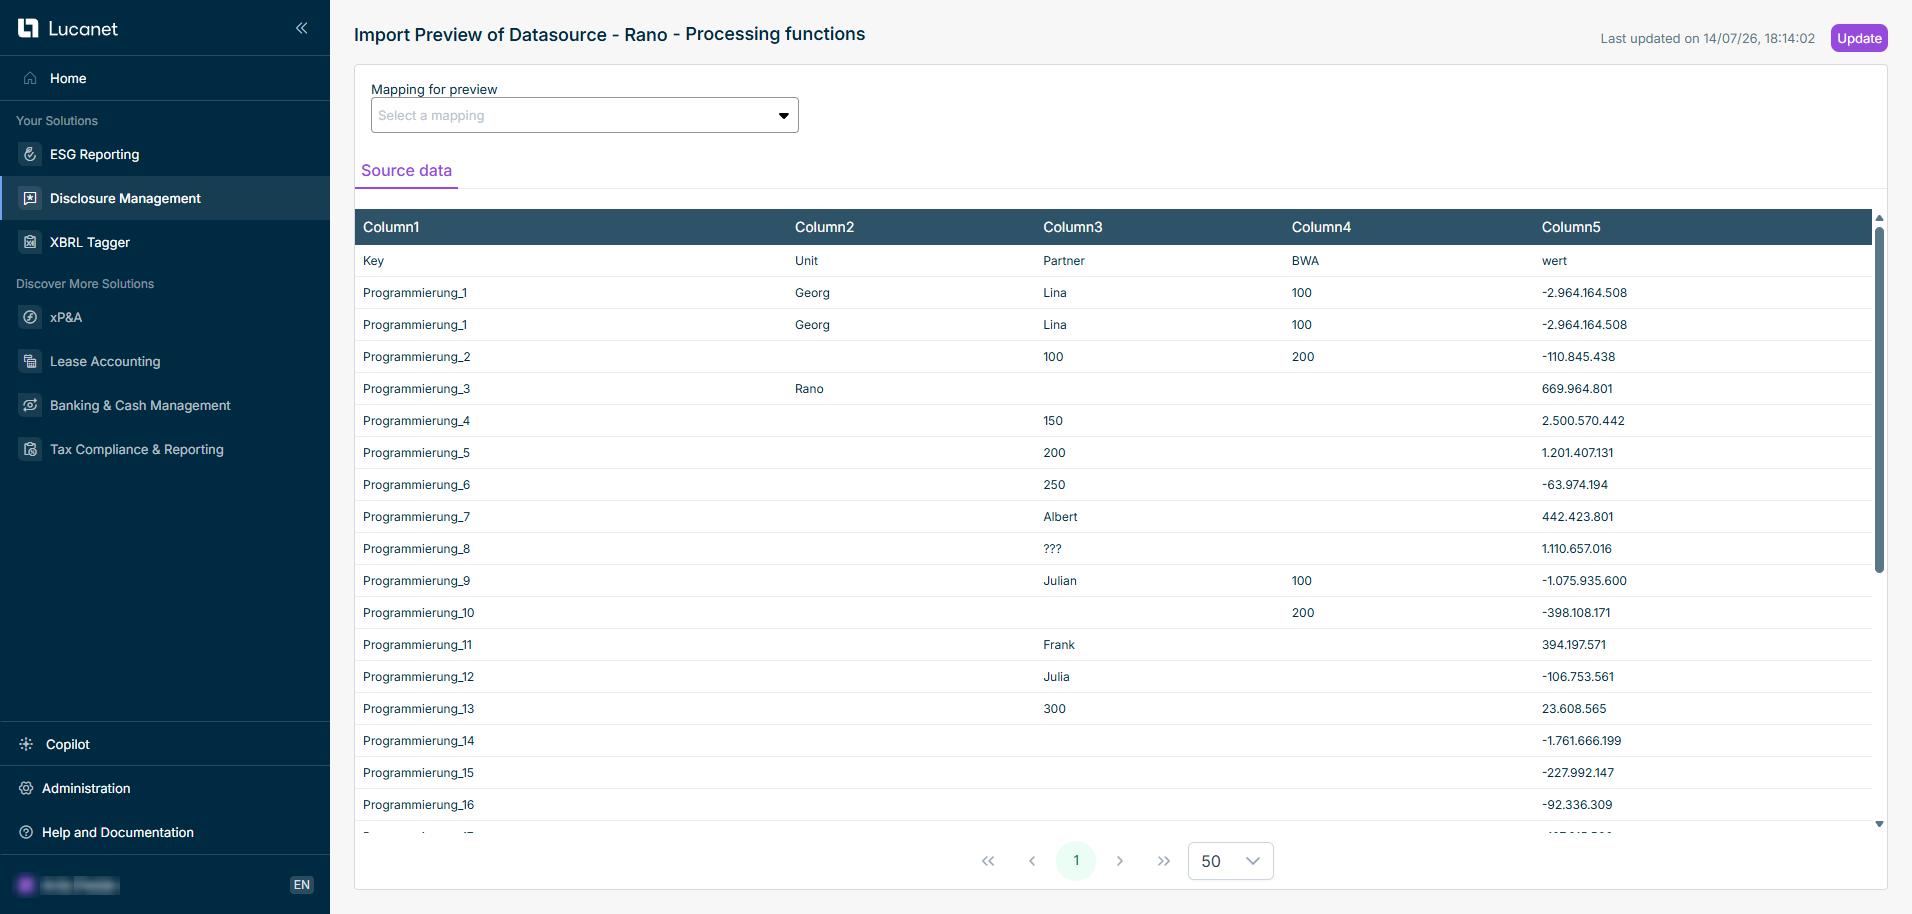
Rows before aggregation:

Shows the 'Source data' tab of the 'Import Preview of Datasource - Rano - Processing functions' window in Disclosure Management with the columns 'Column1' to 'Column5', where 'Column3' contains numeric values, text values and empty cells.
Source data before aggregation 'Filter numeric'

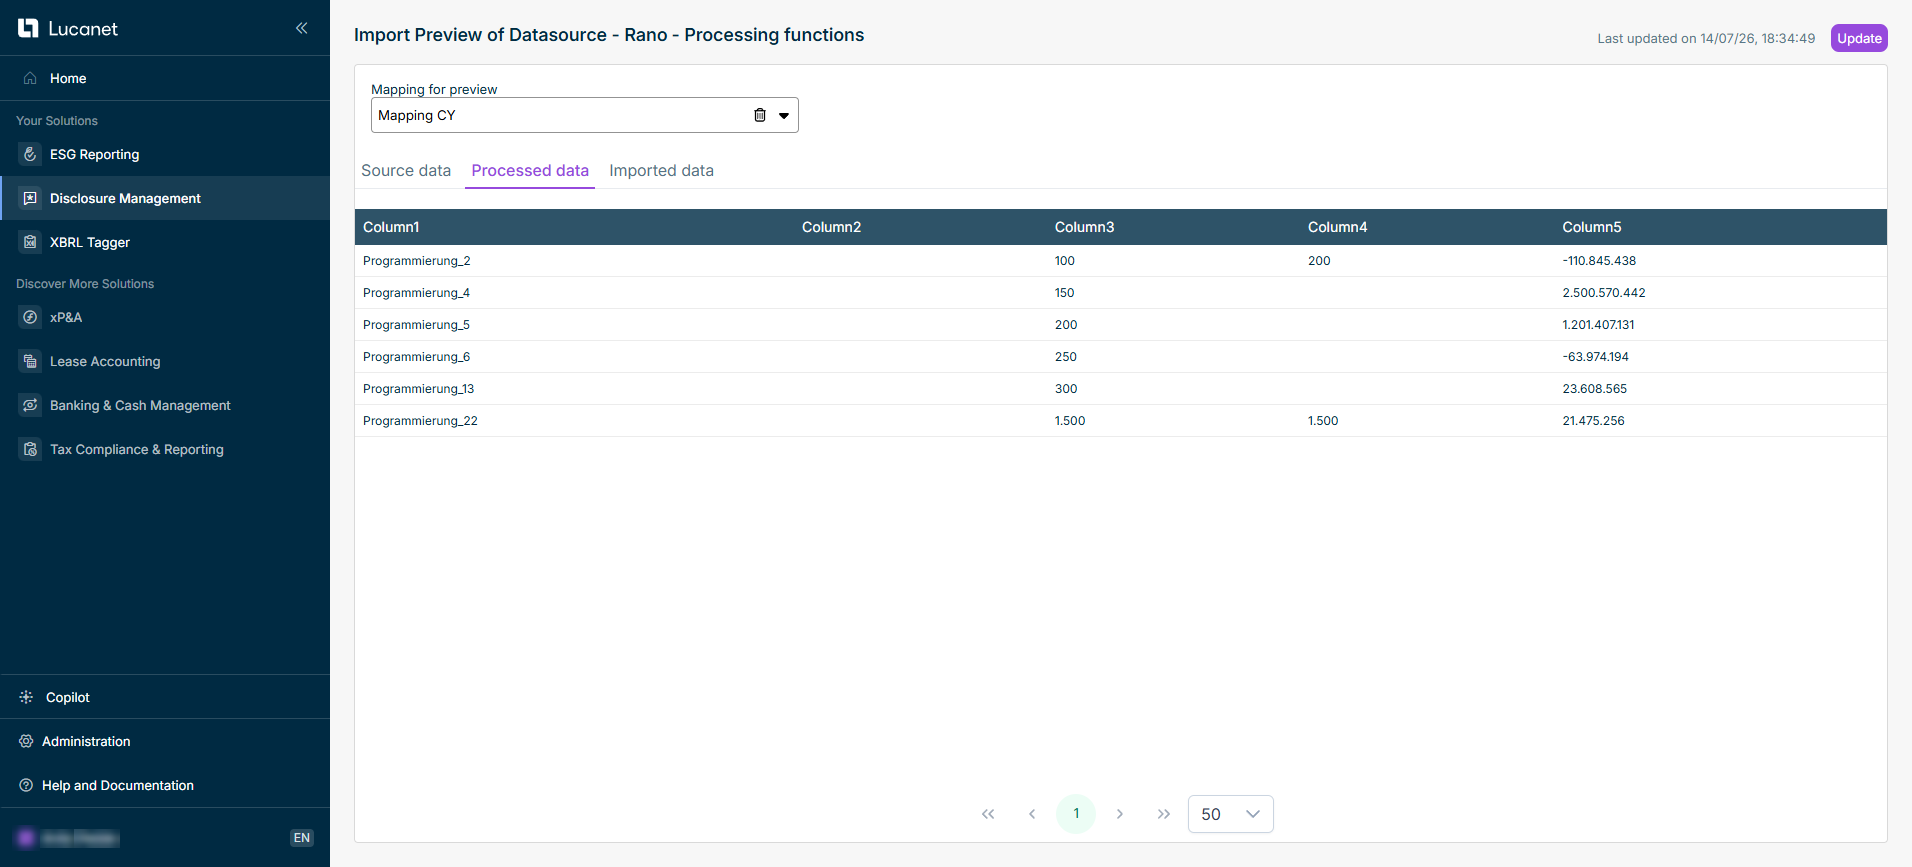
Rows after aggregation:

Shows the 'Processed data' tab of the 'Import Preview of Datasource - Rano - Processing functions' window in Disclosure Management with the mapping 'Mapping CY' and only the rows that have a numeric value in 'Column3'.
Processed data after aggregation 'Filter numeric'

Instead of entering a fixed value, you can have a text parameter of a Disclosure Management data source take its value from a document variable. This is useful when a report is rolled forward: you change the document variable once, instead of editing the value in every affected mapping.

Document variables are supported in the text parameters of the following processing types in Disclosure Management:

Processing typeParameter
FilterFilter
PrefixPrefix
SuffixSuffix
ReplaceRemove text, Insert text

To insert a document variable, write its name between two percent signs — for example %quarter%. To write a literal percent sign, use two percent signs (%%).

A variable can appear anywhere within a parameter, and a parameter can contain more than one. For a document variable year with the value 2025, the filter expression contains "FY%year%" matches rows containing FY2025.

The field shows a hint explaining the syntax, and an unclosed reference such as ="%quarter is reported as a syntax error before you can save.

The stored configuration always keeps the variable, not the value it resolved to. If the document variable quarter changes from Q3 to Q4, the next import filters on Q4 without any change to the mapping.

The value of a document variable is always compared as a single piece of text. It is never interpreted as part of the filter expression.

This matters when a value contains the words and or or, which are otherwise logical operators (see section Filter). A document variable holding Research and Development matches rows whose value is exactly Research and Development — the and is not treated as an operator.

The following also applies to document variables in text parameters:

  • The document variable must exist in the document that the import runs in. If it cannot be resolved, the import fails and names the variable concerned.
  • A document variable with an empty value resolves to an empty text, so the parameter is applied to empty values.
  • In the Import management area, the preview shows the variable as written, for example %quarter%. Import management is not tied to a single document, so no document variables are available there. In a document — in the mapping preview and during the actual import — the variable is resolved as usual.

For information on creating document variables, see Creating and Inserting Document Variables.

To check whether the configured mapping(s) of a Disclosure Management data source are configured correctly and deliver the desired result, you can display a preview of the imported data in a separate window.

To do this, click Open preview in new window in the data source interface.

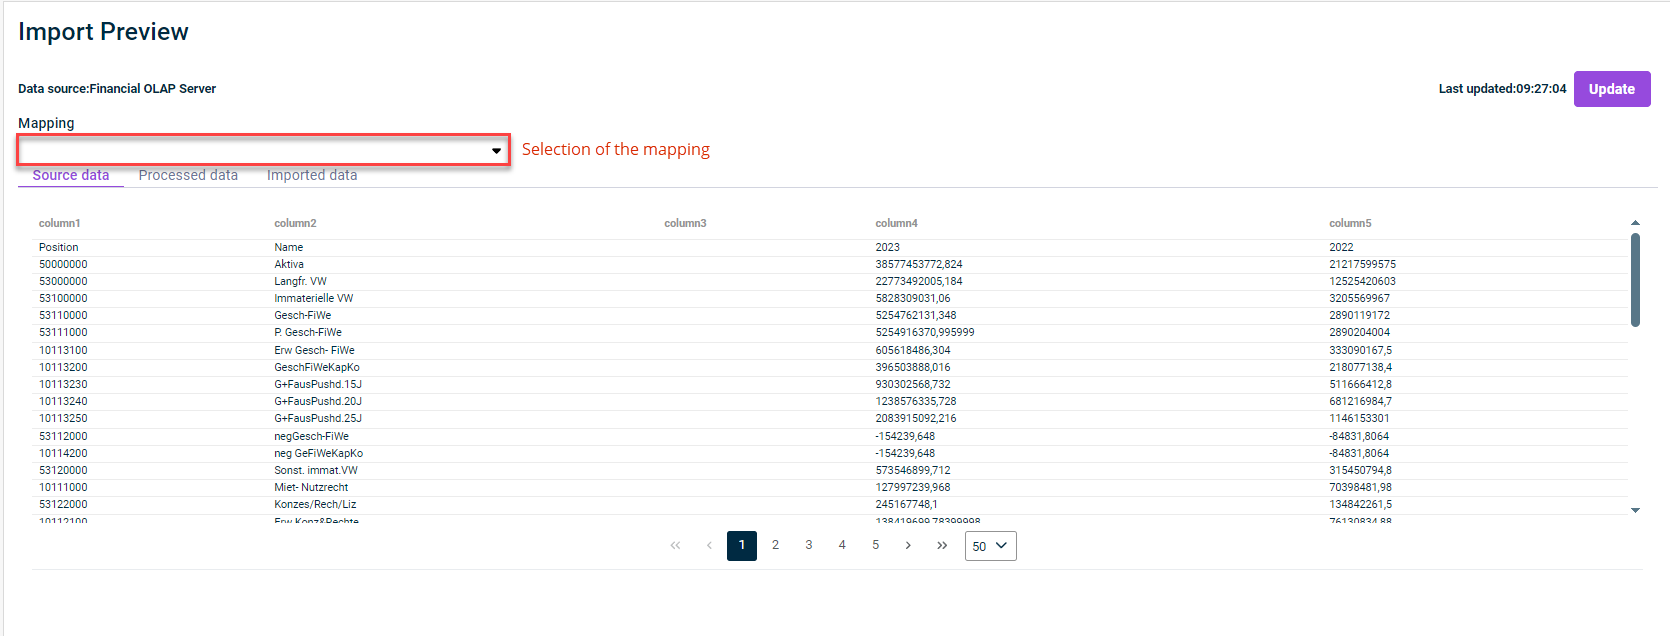
The preview of the imported data is displayed as follows, for example:

Shows the 'Import Preview' window in Disclosure Management for the data source 'Financial OLAP Server' with the tabs 'Source data', 'Processed data' and 'Imported data', the time 'Last updated' and the 'Update' button. Highlighted in red is the drop-down list 'Mapping' with the annotation 'Selection of the mapping'.
Preview of the data import

The following table describes the elements of the import preview in Disclosure Management:

ElementDescription
Import Preview ofName of the data source
Mapping for previewSelection of the mapping for which a preview of the import is to be displayed. All mappings defined in the data source can be selected.
'Source data' tabSource data that serves as the basis for the import
'Processed data' tabPreview of the data after applying transformations and/or aggregations that may have been configured. If no aggregations and/or transformations have been configured, the same data are displayed on this tab as on the Source data tab.
'Imported data' tabPreview of the data that will be imported at the end.
Last updatedTime of the last update of the import preview
UpdateClick this button if you want to execute the import preview again.

To avoid additional configuration effort, a predefined default data source is already available in Disclosure Management for importing report data from Lucanet ESG Reporting.

The following data is imported from an ESG report into Disclosure Management using this data source:

  • The question from the ESG questionnaire in text form (Name column)
  • The unique ID of the entry that is required for programming the Excel file in which the value is to be displayed. (The ID is made up of the number of the question from the ESG questionnaire with the row and column index of the CSV file that is generated in the background when the ESG reporting data is aggregated)
  • The value that is stored in the report for this entry

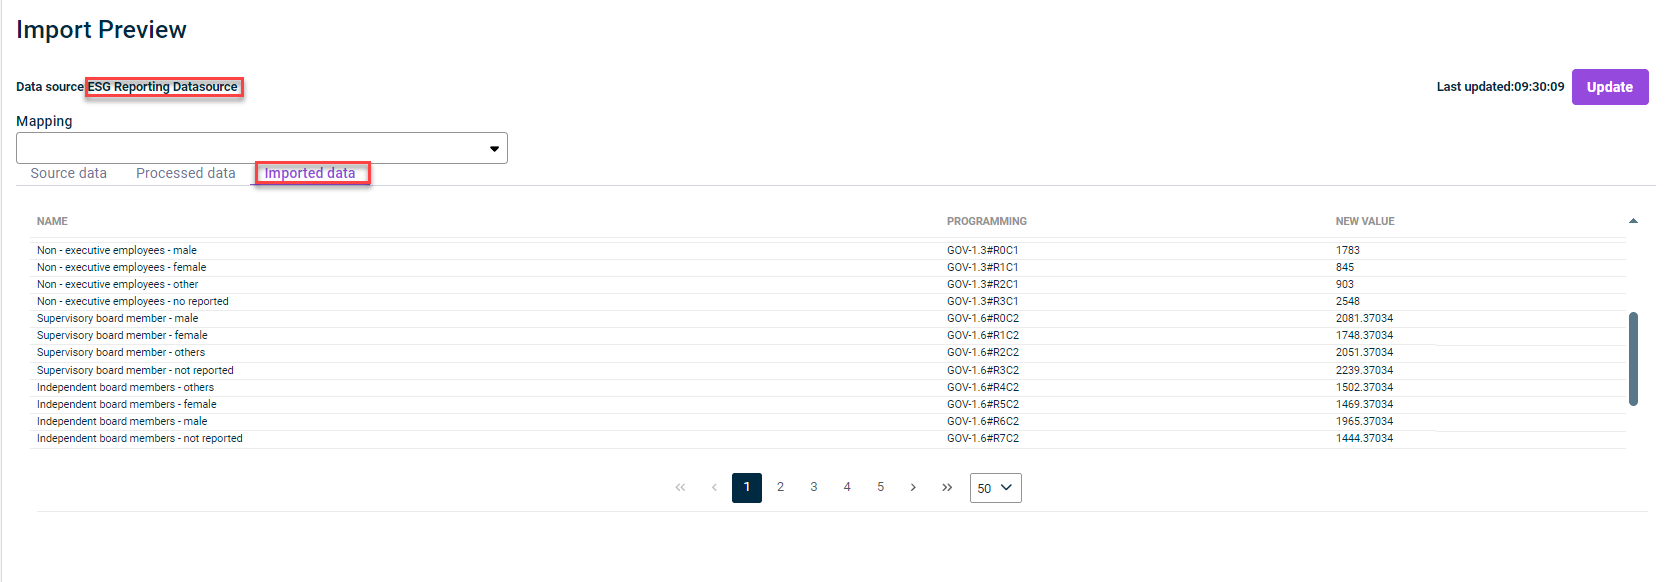
In the Import preview, the imported data is displayed as follows, for example:

Shows the 'Imported data' tab of the 'Import Preview' window in Disclosure Management with the columns 'NAME', 'PROGRAMMING' and 'NEW VALUE', for example 'Supervisory board member - male', 'GOV-1.6#R0C2' and '2081.37034'. Highlighted in red are the data source 'ESG Reporting Datasource' and the 'Imported data' tab.
Example of an import preview with the ESG reporting data source

To use the default data source for importing from Lucanet ESG Reporting into Disclosure Management:
1

Click on the data source ESG Reporting Datasource in the Data sources area.

2

In the Import parameters area, select the ESG report from which you want to import the data from the drop-down list.

3

If necessary, display a preview of the imported data (see Displaying a Preview of the Imported Data).

  • This default data source can be used by all users who have licensed Lucanet ESG Reporting. For all users without a license for Lucanet ESG Reporting, the data source is displayed but cannot be loaded.
  • All reports that have been created in the Lucanet ESG Reporting solution and for which the data has already been aggregated are available for selection. For further information on data aggregation of an ESG report can be found in Aggregating Data chapter of the Lucanet ESG Reporting solution documentation.
  • This default data source cannot be edited any further. To import the above-mentioned data, it already contains a predefined mapping and two predefined transformations.
  • If you want to import data other than the above from an ESG report, you can create a custom data source and define mapping(s) and, if necessary, transformations and/or aggregations as described in the previous sections.

This content was generated using AI and reviewed by Lucanet subject matter experts before publication.